结构热应力仿真-主题065_云计算与仿真即服务-主题065_云计算与仿真即服务教程
主题065:云计算与仿真即服务(SaaS)
目录
引言
1.1 为什么需要云仿真?
随着工程仿真问题的复杂度不断增加,传统的本地计算资源往往难以满足需求:
- 计算资源受限:大型仿真需要数百甚至数千核的并行计算能力
- 硬件投资高昂:高性能计算集群的购置和维护成本巨大
- 资源利用率低:本地集群在空闲时段造成资源浪费
- 协作困难:团队成员难以共享仿真环境和结果
- 扩展性差:难以应对突发的大规模计算需求
云计算为解决这些问题提供了完美的解决方案。通过将仿真任务部署到云端,用户可以:
- 按需获取资源:根据任务需求动态分配计算资源
- 降低初始投资:无需购买昂贵的硬件设备
- 实现弹性伸缩:根据负载自动调整资源规模
- 促进团队协作:通过云端共享仿真数据和结果
- 提高资源利用率:多用户共享云端资源池
1.2 仿真即服务(Simulation as a Service, SaaS)
SaaS是一种软件交付模式,用户通过互联网访问和使用软件应用,而无需关心底层的基础设施。在工程仿真领域,SaaS模式带来了革命性的变化:
传统模式 vs SaaS模式
| 特性 | 传统本地仿真 | 云仿真SaaS |
|---|---|---|
| 硬件投资 | 高昂(购买工作站/集群) | 零初始投资 |
| 软件许可 | 一次性购买或年度订阅 | 按需付费 |
| 维护成本 | 需要专业IT团队 | 由服务商承担 |
| 可扩展性 | 受限于本地硬件 | 几乎无限扩展 |
| 访问方式 | 本地安装 | 浏览器/API访问 |
| 协作能力 | 有限 | 实时协作共享 |
| 数据安全 | 本地控制 | 云端加密存储 |
1.3 学习目标
通过本主题的学习,您将掌握:
- 云计算的基本概念和服务模型(IaaS、PaaS、SaaS)
- 云仿真平台的架构设计原则
- 任务调度算法的原理和实现
- 资源弹性伸缩的策略
- 微服务架构在云仿真中的应用
- REST API的设计与实现
- 云仿真成本分析和优化方法
- 使用Python构建云仿真平台的实战技能
云计算基础概念
2.1 云计算服务模型
云计算提供三种主要的服务模型,形成所谓的"云计算堆栈":
2.1.1 基础设施即服务(IaaS)
IaaS提供最基础的计算资源,包括虚拟机、存储和网络。用户可以在这些基础设施上部署和运行任意软件。
主要特点:
- 完全控制底层基础设施
- 灵活的资源配置
- 按需付费
- 需要自行管理操作系统和应用
典型产品:
- Amazon EC2
- Microsoft Azure VMs
- Google Compute Engine
- 阿里云ECS
在仿真中的应用:
# IaaS层面的仿真资源配置示例
iaas_config = {
    'vm_type': 'compute_optimized',  # 计算优化型实例
    'cpu_cores': 32,
    'memory_gb': 128,
    'storage': {
        'type': 'ssd',
        'size_gb': 500
    },
    'network': {
        'bandwidth_gbps': 10,
        'latency_ms': 1
    }
}
2.1.2 平台即服务(PaaS)
PaaS在IaaS之上提供了应用开发和部署平台,用户无需管理底层基础设施,可以专注于应用开发。
主要特点:
- 预配置的开发环境
- 自动扩展和负载均衡
- 内置数据库和中间件
- 简化部署流程
典型产品:
- Google App Engine
- Heroku
- AWS Elastic Beanstalk
- 阿里云EDAS
在仿真中的应用:
# PaaS层面的仿真平台配置
paas_config = {
    'runtime': 'python3.9',
    'framework': 'flask',
    'services': [
        'postgresql',  # 数据库
        'redis',       # 缓存
        'rabbitmq'     # 消息队列
    ],
    'scaling': {
        'min_instances': 2,
        'max_instances': 20,
        'auto_scaling': True
    }
}
2.1.3 软件即服务(SaaS)
SaaS是最高层的服务模型,用户直接使用提供商的应用软件,无需关心任何技术细节。
主要特点:
- 即开即用
- 自动更新和维护
- 多租户架构
- 订阅制付费
典型仿真SaaS产品:
- OnScale Solve(云端CAE仿真)
- SimScale(基于云的工程仿真)
- Rescale(高性能计算云平台)
- 数巧科技3DLite(国产云仿真平台)
2.2 云部署模型
2.2.1 公有云(Public Cloud)
由第三方云服务提供商拥有和运营,通过互联网向公众提供服务。
优势:
- 成本最低(无需硬件投资)
- 无限扩展能力
- 全球部署
- 最新技术快速迭代
劣势:
- 数据安全和隐私顾虑
- 网络依赖性强
- 定制化程度有限
适用场景:
- 中小企业仿真需求
- 非敏感数据的公开研究
- 临时性、突发性的计算任务
2.2.2 私有云(Private Cloud)
专为单一组织构建,可以部署在本地数据中心或由第三方托管。
优势:
- 最高级别的安全性和控制
- 定制化程度高
- 符合合规要求
- 网络延迟低
劣势:
- 初始投资高
- 需要专业运维团队
- 扩展性受限
适用场景:
- 大型企业的核心仿真业务
- 涉及敏感数据(国防、金融等)
- 需要严格合规的行业
2.2.3 混合云(Hybrid Cloud)
结合公有云和私有云,实现数据和应用的灵活部署。
典型架构:
┌─────────────────────────────────────────────────────────┐
│                    混合云架构                             │
├─────────────────────────────────────────────────────────┤
│                                                         │
│   ┌──────────────┐         ┌──────────────────────┐    │
│   │   私有云      │◄───────►│       公有云          │    │
│   │              │   VPN   │                      │    │
│   │ • 敏感数据    │         │ • 大规模计算          │    │
│   │ • 核心算法    │         │ • 备份存储            │    │
│   │ • 实时仿真    │         │ • 开发测试            │    │
│   └──────────────┘         └──────────────────────┘    │
│                                                         │
│   统一管理平台:OpenStack / VMware / Kubernetes          │
│                                                         │
└─────────────────────────────────────────────────────────┘
优势:
- 兼顾安全性和灵活性
- 成本优化(敏感数据本地,计算任务云端)
- 灾备能力强
适用场景:
- 大型企业的渐进式云迁移
- 需要处理敏感数据的大规模仿真
- 业务负载波动大的场景
2.2.4 多云(Multi-Cloud)
使用多个云服务提供商的服务,避免供应商锁定,优化成本和性能。
策略:
- 最佳服务选择:不同云提供商的优势服务组合
- 成本优化:根据价格动态选择云平台
- 风险分散:避免单一云服务商故障影响
2.3 云仿真的关键技术
2.3.1 容器化技术
Docker容器是云仿真部署的基础技术,它提供了:
- 环境一致性:开发、测试、生产环境完全一致
- 快速部署:秒级启动仿真环境
- 资源隔离:不同仿真任务互不干扰
- 版本控制:仿真环境版本可追溯
# 仿真环境Dockerfile示例
FROM ubuntu:20.04

# 安装依赖
RUN apt-get update && apt-get install -y \
    python3 python3-pip \
    libopenmpi-dev \
    libblas-dev liblapack-dev

# 安装Python包
RUN pip3 install numpy scipy matplotlib fenics

# 复制仿真代码
COPY ./simulation /app/simulation
WORKDIR /app/simulation

# 设置入口点
ENTRYPOINT ["python3", "run_simulation.py"]
2.3.2 容器编排
**Kubernetes(K8s)**是容器编排的事实标准,用于管理大规模容器化应用。
在云仿真中的应用:
# Kubernetes部署配置示例
apiVersion: apps/v1
kind: Deployment
metadata:
  name: simulation-worker
spec:
  replicas: 10  # 10个仿真工作节点
  selector:
    matchLabels:
      app: simulation
  template:
    metadata:
      labels:
        app: simulation
    spec:
      containers:
      - name: simulator
        image: simulation:latest
        resources:
          requests:
            memory: "4Gi"
            cpu: "2"
          limits:
            memory: "8Gi"
            cpu: "4"
        env:
        - name: TASK_QUEUE_URL
          value: "amqp://rabbitmq:5672"
---
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
  name: simulation-hpa
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: simulation-worker
  minReplicas: 5
  maxReplicas: 100
  metrics:
  - type: Resource
    resource:
      name: cpu
      target:
        type: Utilization
        averageUtilization: 70
2.3.3 无服务器计算(Serverless)
无服务器计算让开发者无需管理服务器,只需关注代码逻辑。
在仿真中的应用场景:
- 轻量级预处理/后处理任务
- 事件驱动的结果分析
- 定时任务(如每日仿真报告生成)
# AWS Lambda函数示例:仿真结果处理
import json
import boto3
import numpy as np

def lambda_handler(event, context):
    """
    处理仿真结果文件
    触发条件:S3中生成新的结果文件
    """
    # 获取结果文件
    s3 = boto3.client('s3')
    bucket = event['Records'][0]['s3']['bucket']['name']
    key = event['Records'][0]['s3']['object']['key']

    # 下载并处理数据
    response = s3.get_object(Bucket=bucket, Key=key)
    data = np.load(response['Body'])

    # 计算统计指标
    stats = {
        'max_stress': float(np.max(data)),
        'min_stress': float(np.min(data)),
        'avg_stress': float(np.mean(data)),
        'std_stress': float(np.std(data))
    }

    # 保存统计结果
    result_key = key.replace('raw/', 'stats/').replace('.npy', '.json')
    s3.put_object(
        Bucket=bucket,
        Key=result_key,
        Body=json.dumps(stats)
    )

    return {
        'statusCode': 200,
        'body': json.dumps('Processing completed')
    }
云仿真架构设计
3.1 整体架构概览
一个完整的云仿真平台通常采用分层架构设计:
┌─────────────────────────────────────────────────────────────────┐
│                        用户接入层                                │
│  ┌────────────┐  ┌────────────┐  ┌────────────┐                │
│  │  Web界面   │  │  桌面客户端 │  │  REST API │                │
│  └────────────┘  └────────────┘  └────────────┘                │
└──────────────────────────┬──────────────────────────────────────┘
                           │ HTTPS/WebSocket
┌──────────────────────────▼──────────────────────────────────────┐
│                        网关层                                    │
│              API Gateway / Load Balancer                        │
│         (认证、限流、路由、负载均衡)                             │
└──────────────────────────┬──────────────────────────────────────┘
                           │
┌──────────────────────────▼──────────────────────────────────────┐
│                       应用服务层                                 │
│  ┌──────────┐ ┌──────────┐ ┌──────────┐ ┌──────────┐          │
│  │ 任务服务  │ │ 调度服务  │ │ 资源服务  │ │ 结果服务  │          │
│  └──────────┘ └──────────┘ └──────────┘ └──────────┘          │
└──────────────────────────┬──────────────────────────────────────┘
                           │
┌──────────────────────────▼──────────────────────────────────────┐
│                       消息中间件层                               │
│              Message Queue (RabbitMQ / Kafka / Redis)           │
└──────────────────────────┬──────────────────────────────────────┘
                           │
┌──────────────────────────▼──────────────────────────────────────┐
│                       计算资源层                                 │
│  ┌──────────┐ ┌──────────┐ ┌──────────┐                        │
│  │ 计算节点1 │ │ 计算节点2 │ │ 计算节点N │ ...                   │
│  │ (Docker) │ │ (Docker) │ │ (Docker) │                        │
│  └──────────┘ └──────────┘ └──────────┘                        │
└─────────────────────────────────────────────────────────────────┘
                           │
┌──────────────────────────▼──────────────────────────────────────┐
│                       数据存储层                                 │
│  ┌──────────────┐ ┌──────────────┐ ┌──────────────┐            │
│  │  对象存储     │ │  关系数据库   │ │   缓存       │            │
│  │  (S3/MinIO)  │ │ (PostgreSQL) │ │  (Redis)    │            │
│  └──────────────┘ └──────────────┘ └──────────────┘            │
└─────────────────────────────────────────────────────────────────┘
3.2 核心组件详解
3.2.1 任务服务(Task Service)
负责任务的全生命周期管理:
核心功能:
- 任务提交与验证
- 任务状态查询
- 任务取消与重试
- 任务优先级管理
- 任务历史记录
数据模型:
class SimulationTask:
    """
    仿真任务数据模型
    """
    def __init__(self, task_type, params, priority=5):
        self.task_id = generate_uuid()           # 唯一标识
        self.task_type = task_type               # 任务类型
        self.params = params                     # 仿真参数
        self.priority = priority                 # 优先级(1-10)
        self.status = TaskStatus.PENDING         # 任务状态

        # 时间戳
        self.created_at = datetime.now()         # 创建时间
        self.started_at = None                   # 开始时间
        self.completed_at = None                 # 完成时间

        # 资源需求
        self.estimated_cpu = self._estimate_cpu()
        self.estimated_memory = self._estimate_memory()
        self.estimated_time = self._estimate_time()

        # 执行信息
        self.assigned_node = None                # 分配的节点
        self.result_url = None                   # 结果存储位置
        self.error_message = None                # 错误信息
3.2.2 调度服务(Scheduler Service)
负责将任务分配到合适的计算节点:
调度策略:
-
先来先服务(FIFO)
- 按照任务提交顺序执行
- 简单公平,但可能导致短任务等待长任务
-
优先级调度
- 高优先级任务优先执行
- 适用于紧急任务或VIP用户
- 可能导致低优先级任务饥饿
-
最短作业优先(SJF)
- 预估执行时间最短的任务优先
- 最小化平均等待时间
- 需要准确的时间预估
-
公平共享调度
- 按用户/项目组分配资源配额
- 确保资源公平使用
- 适用于多租户环境
-
资源感知调度
- 考虑任务的资源需求和节点的资源状况
- 最大化资源利用率
- 避免资源碎片
调度算法实现:
class TaskScheduler:
    """
    任务调度器
    """
    def __init__(self, policy='priority'):
        self.policy = policy
        self.task_queue = []

    def submit_task(self, task):
        """提交任务到队列"""
        self.task_queue.append(task)
        self._sort_queue()

    def _sort_queue(self):
        """根据调度策略排序"""
        if self.policy == 'priority':
            # 优先级 + 提交时间
            self.task_queue.sort(
                key=lambda t: (t.priority, t.created_at)
            )
        elif self.policy == 'fifo':
            # 仅按提交时间
            self.task_queue.sort(key=lambda t: t.created_at)
        elif self.policy == 'sjf':
            # 最短作业优先
            self.task_queue.sort(
                key=lambda t: (t.estimated_time, t.priority)
            )

    def schedule(self, compute_nodes):
        """
        将任务调度到计算节点

        使用最佳适配算法(Best Fit)
        """
        scheduled = []

        for task in self.task_queue[:]:
            # 找到能满足资源需求且剩余资源最少的节点
            best_node = None
            min_remaining = float('inf')

            for node in compute_nodes:
                if node.can_accept(task):
                    remaining = node.available_cpu - task.estimated_cpu
                    if remaining < min_remaining:
                        min_remaining = remaining
                        best_node = node

            if best_node:
                best_node.assign_task(task)
                self.task_queue.remove(task)
                scheduled.append((task, best_node))

        return scheduled
3.2.3 资源服务(Resource Service)
负责计算资源的管理和监控:
核心功能:
- 节点注册与发现
- 健康检查与故障恢复
- 资源监控与告警
- 弹性伸缩控制
- 成本追踪
节点管理:
class ComputeNode:
    """
    计算节点
    """
    def __init__(self, node_id, cpu_cores, memory_gb):
        self.node_id = node_id
        self.total_cpu = cpu_cores
        self.total_memory = memory_gb

        # 可用资源
        self.available_cpu = cpu_cores
        self.available_memory = memory_gb

        # 状态
        self.status = 'online'           # online/offline/busy
        self.running_tasks = []
        self.health_score = 100          # 健康评分

        # 性能指标
        self.cpu_utilization_history = []
        self.memory_utilization_history = []

    def update_metrics(self):
        """更新节点性能指标"""
        cpu_util = 1 - self.available_cpu / self.total_cpu
        mem_util = 1 - self.available_memory / self.total_memory

        self.cpu_utilization_history.append(cpu_util)
        self.memory_utilization_history.append(mem_util)

        # 保持历史记录在合理长度
        if len(self.cpu_utilization_history) > 100:
            self.cpu_utilization_history.pop(0)
            self.memory_utilization_history.pop(0)

    def get_average_utilization(self, window=10):
        """获取平均利用率"""
        if not self.cpu_utilization_history:
            return 0, 0

        recent_cpu = self.cpu_utilization_history[-window:]
        recent_mem = self.memory_utilization_history[-window:]

        return np.mean(recent_cpu), np.mean(recent_mem)
3.2.4 结果服务(Result Service)
负责仿真结果的存储、管理和可视化:
核心功能:
- 结果文件存储(支持大文件分片上传)
- 结果元数据管理
- 结果检索与下载
- 结果可视化(在线查看)
- 结果分享与权限控制
存储策略:
class ResultStorage:
    """
    结果存储管理
    """
    def __init__(self, storage_backend='s3'):
        self.backend = storage_backend
        self.metadata_db = PostgreSQL()  # 元数据数据库

    def store_result(self, task_id, result_data, metadata):
        """
        存储仿真结果

        策略:
        1. 小文件(<100MB):直接存储
        2. 大文件(>=100MB):分片存储
        """
        file_size = len(result_data)

        if file_size < 100 * 1024 * 1024:  # 100MB
            # 直接存储
            storage_path = f"results/{task_id}/result.dat"
            self._upload_file(storage_path, result_data)
        else:
            # 分片存储
            chunks = self._split_file(result_data, chunk_size=50*1024*1024)
            for i, chunk in enumerate(chunks):
                chunk_path = f"results/{task_id}/chunks/part_{i:04d}"
                self._upload_file(chunk_path, chunk)
            storage_path = f"results/{task_id}/manifest.json"

        # 保存元数据
        self.metadata_db.insert({
            'task_id': task_id,
            'storage_path': storage_path,
            'file_size': file_size,
            'created_at': datetime.now(),
            **metadata
        })

        return storage_path

    def retrieve_result(self, task_id):
        """检索结果"""
        metadata = self.metadata_db.query(task_id=task_id)

        if metadata['storage_path'].endswith('manifest.json'):
            # 分片文件,需要合并
            return self._merge_chunks(metadata['storage_path'])
        else:
            # 直接下载
            return self._download_file(metadata['storage_path'])
任务调度算法
4.1 调度问题概述
云仿真平台的任务调度是一个复杂的优化问题,需要考虑多个目标:
优化目标:
- 最小化任务完成时间(Makespan)
- 最小化平均等待时间
- 最大化资源利用率
- 保证公平性
- 满足截止时间约束
约束条件:
- 任务资源需求(CPU、内存、GPU)
- 任务依赖关系
- 数据局部性(数据存储位置)
- 用户优先级和配额
4.2 经典调度算法
4.2.1 先来先服务(FCFS)
最简单的调度算法,按任务到达顺序执行。
优点:
- 实现简单
- 无饥饿问题
- 公平性好
缺点:
- 平均等待时间长
- 资源利用率低
- 短任务可能被长任务阻塞
适用场景:
- 批处理作业
- 负载相对均匀的环境
def fcfs_schedule(tasks, nodes):
    """先来先服务调度"""
    schedule = []
    node_available_time = {node.id: 0 for node in nodes}

    for task in sorted(tasks, key=lambda t: t.arrival_time):
        # 找到最早可用的节点
        earliest_node = min(nodes,
                          key=lambda n: node_available_time[n.id])

        start_time = max(task.arrival_time,
                        node_available_time[earliest_node.id])
        completion_time = start_time + task.duration

        schedule.append({
            'task': task,
            'node': earliest_node,
            'start': start_time,
            'completion': completion_time
        })

        node_available_time[earliest_node.id] = completion_time

    return schedule
4.2.2 最短作业优先(SJF)
优先执行预估执行时间最短的任务。
优点:
- 最小化平均等待时间
- 提高系统吞吐量
缺点:
- 需要准确的时间预估
- 长任务可能饥饿
- 不适合实时到达的任务
改进:最短剩余时间优先(SRTF)
- 支持抢占
- 新到达的短任务可以抢占正在执行的长任务
def sjf_schedule(tasks, nodes):
    """最短作业优先调度(非抢占式)"""
    schedule = []
    current_time = 0
    remaining_tasks = list(tasks)

    while remaining_tasks:
        # 找到已到达且执行时间最短的任务
        available_tasks = [
            t for t in remaining_tasks
            if t.arrival_time <= current_time
        ]

        if not available_tasks:
            # 没有可用任务,跳到下一个到达时间
            current_time = min(t.arrival_time for t in remaining_tasks)
            continue

        # 选择最短作业
        task = min(available_tasks, key=lambda t: t.duration)

        # 分配到第一个可用节点
        node = nodes[len(schedule) % len(nodes)]

        start_time = max(current_time, task.arrival_time)
        completion_time = start_time + task.duration

        schedule.append({
            'task': task,
            'node': node,
            'start': start_time,
            'completion': completion_time
        })

        current_time = completion_time
        remaining_tasks.remove(task)

    return schedule
4.2.3 优先级调度
根据任务优先级进行调度。
优先级确定因素:
- 用户等级(VIP用户优先)
- 任务紧急程度
- 任务资源需求
- 等待时间(防止饥饿)
** aging技术**:
长时间等待的任务逐渐增加优先级,防止饥饿。
class PriorityScheduler:
    """
    优先级调度器(带aging机制)
    """
    def __init__(self, aging_factor=0.1):
        self.aging_factor = aging_factor  # 老化系数

    def calculate_priority(self, task, current_time):
        """
        计算动态优先级

        动态优先级 = 基础优先级 - aging系数 × 等待时间
        """
        waiting_time = current_time - task.arrival_time
        dynamic_priority = (
            task.base_priority -
            self.aging_factor * waiting_time
        )
        return dynamic_priority

    def schedule(self, tasks, nodes, current_time):
        """优先级调度"""
        # 计算所有任务的动态优先级
        task_priorities = [
            (task, self.calculate_priority(task, current_time))
            for task in tasks
        ]

        # 按优先级排序(数值小的优先级高)
        task_priorities.sort(key=lambda x: x[1])

        # 分配任务到节点
        schedule = []
        for task, _ in task_priorities:
            # 找到能满足资源需求的最佳节点
            suitable_nodes = [
                n for n in nodes
                if n.can_accept(task)
            ]

            if suitable_nodes:
                # 选择负载最轻的节点
                node = min(suitable_nodes,
                          key=lambda n: n.load)
                schedule.append({'task': task, 'node': node})

        return schedule
4.2.4 负载均衡调度
将任务均匀分布到各个节点,避免某些节点过载。
常用算法:
-
轮询(Round Robin)
- 依次将任务分配给每个节点
- 简单但不考虑节点差异
-
最小连接数(Least Connections)
- 将任务分配给当前连接数/任务数最少的节点
- 适合长连接场景
-
加权轮询/最小连接
- 考虑节点性能差异
- 高性能节点分配更多任务
-
一致性哈希
- 相同类型的任务分配到相同节点
- 提高缓存命中率
class LoadBalancer:
    """
    负载均衡调度器
    """
    def __init__(self, algorithm='weighted_least_connections'):
        self.algorithm = algorithm
        self.node_weights = {}  # 节点权重

    def round_robin(self, tasks, nodes):
        """轮询调度"""
        schedule = []
        node_index = 0

        for task in tasks:
            node = nodes[node_index % len(nodes)]
            schedule.append({'task': task, 'node': node})
            node_index += 1

        return schedule

    def weighted_least_connections(self, tasks, nodes):
        """加权最小连接数调度"""
        schedule = []

        for task in tasks:
            # 计算每个节点的负载分数
            # 分数 = 当前任务数 / 权重
            node_scores = [
                (node, node.running_task_count /
                 self.node_weights.get(node.id, 1))
                for node in nodes
                if node.can_accept(task)
            ]

            if node_scores:
                # 选择分数最小的节点
                best_node = min(node_scores, key=lambda x: x[1])[0]
                schedule.append({'task': task, 'node': best_node})
                best_node.running_task_count += 1

        return schedule

    def consistent_hash(self, tasks, nodes):
        """一致性哈希调度"""
        import hashlib

        def get_hash(key):
            return int(hashlib.md5(key.encode()).hexdigest(), 16)

        # 构建哈希环
        hash_ring = []
        for node in nodes:
            # 每个节点在环上有多个虚拟节点
            for i in range(150):  # 虚拟节点数
                hash_val = get_hash(f"{node.id}:{i}")
                hash_ring.append((hash_val, node))

        hash_ring.sort()

        schedule = []
        for task in nodes:
            task_hash = get_hash(task.id)

            # 找到顺时针方向的第一个节点
            for hash_val, node in hash_ring:
                if hash_val >= task_hash:
                    if node.can_accept(task):
                        schedule.append({'task': task, 'node': node})
                    break

        return schedule
4.3 启发式调度算法
对于复杂的调度问题,可以使用启发式算法寻找近似最优解。
4.3.1 遗传算法(Genetic Algorithm)
模拟自然选择过程,通过遗传操作(选择、交叉、变异)优化调度方案。
class GeneticScheduler:
    """
    基于遗传算法的任务调度器
    """
    def __init__(self, population_size=100, generations=50):
        self.population_size = population_size
        self.generations = generations

    def encode_chromosome(self, schedule):
        """
        编码:将调度方案编码为染色体
        染色体 = [任务1的节点ID, 任务2的节点ID, ...]
        """
        return [s['node'].id for s in schedule]

    def decode_chromosome(self, chromosome, tasks, nodes):
        """解码:将染色体解码为调度方案"""
        node_map = {n.id: n for n in nodes}
        return [
            {'task': task, 'node': node_map[node_id]}
            for task, node_id in zip(tasks, chromosome)
        ]

    def fitness(self, chromosome, tasks, nodes):
        """
        适应度函数
        目标:最小化完成时间和资源不平衡度
        """
        schedule = self.decode_chromosome(chromosome, tasks, nodes)

        # 计算完成时间
        node_completion_times = {}
        for s in schedule:
            node_id = s['node'].id
            start_time = node_completion_times.get(node_id, 0)
            completion_time = start_time + s['task'].duration
            node_completion_times[node_id] = completion_time

        makespan = max(node_completion_times.values())

        # 计算资源不平衡度(标准差)
        completion_times = list(node_completion_times.values())
        imbalance = np.std(completion_times)

        # 适应度 = 1 / (完成时间 + 不平衡度惩罚)
        fitness = 1 / (makespan + 0.1 * imbalance)

        return fitness

    def crossover(self, parent1, parent2):
        """交叉操作:单点交叉"""
        point = random.randint(1, len(parent1) - 1)
        child1 = parent1[:point] + parent2[point:]
        child2 = parent2[:point] + parent1[point:]
        return child1, child2

    def mutate(self, chromosome, nodes, mutation_rate=0.1):
        """变异操作:随机改变某些任务的分配节点"""
        mutated = chromosome[:]
        for i in range(len(mutated)):
            if random.random() < mutation_rate:
                mutated[i] = random.choice([n.id for n in nodes])
        return mutated

    def schedule(self, tasks, nodes):
        """遗传算法主流程"""
        # 初始化种群
        population = []
        for _ in range(self.population_size):
            chromosome = [random.choice(nodes).id for _ in tasks]
            population.append(chromosome)

        # 进化
        for generation in range(self.generations):
            # 计算适应度
            fitness_scores = [
                self.fitness(chrom, tasks, nodes)
                for chrom in population
            ]

            # 选择(轮盘赌选择)
            selected = self.roulette_wheel_selection(
                population, fitness_scores
            )

            # 交叉和变异
            next_generation = []
            for i in range(0, len(selected), 2):
                parent1 = selected[i]
                parent2 = selected[i + 1] if i + 1 < len(selected) else selected[0]

                child1, child2 = self.crossover(parent1, parent2)
                child1 = self.mutate(child1, nodes)
                child2 = self.mutate(child2, nodes)

                next_generation.extend([child1, child2])

            population = next_generation[:self.population_size]

        # 返回最优解
        best_chromosome = max(population,
                            key=lambda c: self.fitness(c, tasks, nodes))
        return self.decode_chromosome(best_chromosome, tasks, nodes)
4.3.2 模拟退火算法(Simulated Annealing)
模拟物理退火过程,通过接受劣解来跳出局部最优。
class SimulatedAnnealingScheduler:
    """
    基于模拟退火的任务调度器
    """
    def __init__(self, initial_temp=100, cooling_rate=0.95):
        self.initial_temp = initial_temp
        self.cooling_rate = cooling_rate

    def objective(self, schedule):
        """目标函数:最小化完成时间"""
        node_completion_times = {}
        for s in schedule:
            node_id = s['node'].id
            start = node_completion_times.get(node_id, 0)
            node_completion_times[node_id] = start + s['task'].duration
        return max(node_completion_times.values())

    def neighbor(self, schedule, nodes):
        """生成邻域解:随机改变一个任务的分配"""
        new_schedule = schedule[:]
        idx = random.randint(0, len(new_schedule) - 1)
        new_schedule[idx]['node'] = random.choice(nodes)
        return new_schedule

    def schedule(self, tasks, nodes, max_iterations=1000):
        """模拟退火主流程"""
        # 初始解:随机分配
        current_schedule = [
            {'task': task, 'node': random.choice(nodes)}
            for task in tasks
        ]
        current_cost = self.objective(current_schedule)

        best_schedule = current_schedule
        best_cost = current_cost

        temperature = self.initial_temp

        for iteration in range(max_iterations):
            # 生成邻域解
            new_schedule = self.neighbor(current_schedule, nodes)
            new_cost = self.objective(new_schedule)

            # 计算接受概率
            delta = new_cost - current_cost
            if delta < 0:
                # 优解一定接受
                accept = True
            else:
                # 劣解以一定概率接受
                accept = random.random() < math.exp(-delta / temperature)

            if accept:
                current_schedule = new_schedule
                current_cost = new_cost

                if current_cost < best_cost:
                    best_schedule = current_schedule
                    best_cost = current_cost

            # 降温
            temperature *= self.cooling_rate

        return best_schedule
资源管理与弹性伸缩
5.1 资源监控
有效的资源管理建立在全面的监控基础之上。
5.1.1 监控指标
系统级指标:
- CPU利用率(整体和每个核心)
- 内存使用量和利用率
- 磁盘I/O(读写速率、IOPS)
- 网络带宽(入站/出站)
- GPU利用率(如果使用GPU)
应用级指标:
- 任务队列长度
- 任务执行时间
- 任务成功率
- API响应时间
- 并发用户数
业务级指标:
- 资源成本
- 用户满意度
- 任务吞吐量
5.1.2 监控架构
┌─────────────────────────────────────────────────────────────┐
│                      监控数据流                              │
├─────────────────────────────────────────────────────────────┤
│                                                             │
│   计算节点                    监控收集层          存储与分析  │
│  ┌──────────┐               ┌──────────┐      ┌──────────┐ │
│  │ Node Exporter│──────────►│ Prometheus│─────►│ InfluxDB │ │
│  │ (系统指标)  │              │ (时序数据库)│      │ (时序数据)│ │
│  └──────────┘               └──────────┘      └────┬─────┘ │
│       │                                            │       │
│  ┌──────────┐               ┌──────────┐           │       │
│  │ App Metrics│────────────►│  Kafka   │───────────┘       │
│  │ (应用指标)  │              │ (消息队列)│                   │
│  └──────────┘               └──────────┘                   │
│                                                             │
│                                    ┌──────────┐            │
│                                    │  Grafana │            │
│                                    │(可视化)  │            │
│                                    └──────────┘            │
│                                                             │
└─────────────────────────────────────────────────────────────┘
5.2 弹性伸缩策略
弹性伸缩(Auto Scaling)是云计算的核心特性,可以根据负载自动调整资源规模。
5.2.1 伸缩类型
水平伸缩(Scale Out/In):
- 增加或减少实例数量
- 适合无状态服务
- 扩展性好,但管理复杂
垂直伸缩(Scale Up/Down):
- 增加或减少单个实例的资源(CPU、内存)
- 适合有状态服务
- 简单但有上限
5.2.2 伸缩策略
基于阈值的策略:
class ThresholdBasedAutoscaler:
    """
    基于阈值的自动伸缩器
    """
    def __init__(self):
        self.scale_up_threshold = 0.8    # CPU利用率超过80%扩容
        self.scale_down_threshold = 0.2  # CPU利用率低于20%缩容
        self.scale_up_cooldown = 300     # 扩容冷却时间(秒)
        self.scale_down_cooldown = 600   # 缩容冷却时间(秒)

        self.last_scale_up = 0
        self.last_scale_down = 0

    def evaluate(self, metrics):
        """
        评估是否需要伸缩

        返回: 'scale_up', 'scale_down', 或 'no_action'
        """
        current_time = time.time()
        avg_cpu = metrics['avg_cpu_utilization']
        queue_length = metrics['queue_length']

        # 扩容判断
        if (avg_cpu > self.scale_up_threshold or
            queue_length > 10):
            if current_time - self.last_scale_up > self.scale_up_cooldown:
                self.last_scale_up = current_time
                return 'scale_up'

        # 缩容判断
        if avg_cpu < self.scale_down_threshold and queue_length == 0:
            if current_time - self.last_scale_down > self.scale_down_cooldown:
                self.last_scale_down = current_time
                return 'scale_down'

        return 'no_action'
基于预测的策略:
class PredictiveAutoscaler:
    """
    基于负载预测的自动伸缩器
    """
    def __init__(self, prediction_horizon=300):
        self.prediction_horizon = prediction_horizon  # 预测时间窗口(秒)
        self.history = []  # 历史负载数据

    def predict_load(self):
        """
        使用简单线性回归预测未来负载
        """
        if len(self.history) < 10:
            return None

        # 准备数据
        X = np.array(range(len(self.history))).reshape(-1, 1)
        y = np.array(self.history)

        # 线性回归
        from sklearn.linear_model import LinearRegression
        model = LinearRegression()
        model.fit(X, y)

        # 预测
        future_x = len(self.history) + self.prediction_horizon / 60
        predicted_load = model.predict([[future_x]])[0]

        return predicted_load

    def evaluate(self, current_metrics):
        """评估伸缩需求"""
        # 记录历史
        self.history.append(current_metrics['avg_cpu_utilization'])
        if len(self.history) > 100:
            self.history.pop(0)

        # 预测
        predicted_load = self.predict_load()
        if predicted_load is None:
            return 'no_action'

        # 根据预测决定伸缩
        current_nodes = current_metrics['total_nodes']

        if predicted_load > 0.8:
            # 预测负载高,提前扩容
            needed_nodes = int(current_nodes * predicted_load / 0.6)
            return f'scale_up_to_{needed_nodes}'
        elif predicted_load < 0.3 and current_nodes > 1:
            # 预测负载低,提前缩容
            needed_nodes = max(1, int(current_nodes * predicted_load / 0.5))
            return f'scale_down_to_{needed_nodes}'

        return 'no_action'
基于成本的优化策略:
class CostOptimizedAutoscaler:
    """
    成本优化的自动伸缩器

    综合考虑性能和成本,寻找最优资源配置
    """
    def __init__(self):
        self.on_demand_cost = 0.10  # $/核/小时
        self.spot_cost = 0.03       # $/核/小时(Spot实例)
        self.sla_target = 300       # 目标响应时间(秒)

    def calculate_cost(self, num_on_demand, num_spot, duration_hours):
        """计算总成本"""
        return (num_on_demand * self.on_demand_cost +
                num_spot * self.spot_cost) * duration_hours

    def evaluate(self, metrics, task_queue):
        """
        评估最优资源配置

        策略:
        1. 基础负载使用预留实例
        2. 波动负载使用按需实例
        3. 可容错任务使用Spot实例
        """
        current_nodes = metrics['total_nodes']
        queue_length = metrics['queue_length']
        avg_wait_time = metrics['avg_wait_time']

        # 如果等待时间过长,需要扩容
        if avg_wait_time > self.sla_target:
            # 优先使用Spot实例(成本低)
            spot_nodes = min(queue_length, 10)  # 最多10个Spot
            on_demand_nodes = 1

            return {
                'action': 'scale_up',
                'on_demand': on_demand_nodes,
                'spot': spot_nodes
            }

        # 如果资源利用率低,考虑缩容
        if metrics['cpu_utilization'] < 0.2 and current_nodes > 2:
            # 优先释放Spot实例
            return {
                'action': 'scale_down',
                'release_spot_first': True,
                'target_nodes': max(2, current_nodes - 2)
            }

        return {'action': 'no_action'}
5.3 资源配额管理
在多租户环境中,需要为不同用户或项目组分配资源配额。
class ResourceQuotaManager:
    """
    资源配额管理器
    """
    def __init__(self):
        self.quotas = {}  # 用户配额
        self.usage = {}   # 当前使用情况

    def set_quota(self, user_id, quota):
        """
        设置用户配额

        quota = {
            'max_cpu_cores': 100,      # 最大CPU核心数
            'max_memory_gb': 500,       # 最大内存
            'max_concurrent_tasks': 20, # 最大并发任务数
            'monthly_budget': 1000      # 月度预算($)
        }
        """
        self.quotas[user_id] = quota
        self.usage[user_id] = {
            'cpu_cores': 0,
            'memory_gb': 0,
            'concurrent_tasks': 0,
            'monthly_cost': 0
        }

    def check_quota(self, user_id, requested_resources):
        """检查是否超出配额"""
        if user_id not in self.quotas:
            return False, "用户未设置配额"

        quota = self.quotas[user_id]
        current = self.usage[user_id]

        # 检查各项资源
        if current['cpu_cores'] + requested_resources['cpu'] > quota['max_cpu_cores']:
            return False, "超出CPU配额"

        if current['memory_gb'] + requested_resources['memory'] > quota['max_memory_gb']:
            return False, "超出内存配额"

        if current['concurrent_tasks'] + 1 > quota['max_concurrent_tasks']:
            return False, "超出并发任务数配额"

        return True, "配额检查通过"

    def allocate_resources(self, user_id, resources):
        """分配资源"""
        can_allocate, message = self.check_quota(user_id, resources)

        if can_allocate:
            self.usage[user_id]['cpu_cores'] += resources['cpu']
            self.usage[user_id]['memory_gb'] += resources['memory']
            self.usage[user_id]['concurrent_tasks'] += 1

        return can_allocate, message

    def release_resources(self, user_id, resources):
        """释放资源"""
        self.usage[user_id]['cpu_cores'] -= resources['cpu']
        self.usage[user_id]['memory_gb'] -= resources['memory']
        self.usage[user_id]['concurrent_tasks'] -= 1
微服务架构
6.1 微服务设计原则
6.1.1 单一职责原则
每个微服务应该只负责一个明确的业务功能。
云仿真平台的微服务划分:
| 服务名称 | 职责 | 独立部署 | 技术栈 |
|---|---|---|---|
| Task Service | 任务生命周期管理 | 是 | Python/FastAPI |
| Scheduler Service | 任务调度 | 是 | Python/Celery |
| Resource Service | 资源管理 | 是 | Python/Flask |
| Result Service | 结果管理 | 是 | Python/FastAPI |
| Auth Service | 认证授权 | 是 | Go/Node.js |
| Notification Service | 通知服务 | 是 | Python/Celery |
| Billing Service | 计费服务 | 是 | Python/Django |
6.1.2 服务间通信
同步通信(REST/gRPC):
- 适合实时性要求高的场景
- 简单直接,但存在耦合
# REST API调用示例
import requests

def submit_task_to_scheduler(task_data):
    """调用Scheduler Service提交任务"""
    response = requests.post(
        'http://scheduler-service:8080/api/v1/schedule',
        json=task_data,
        timeout=30
    )
    return response.json()
异步通信(消息队列):
- 适合解耦和削峰填谷
- 提高系统弹性和可用性
# 使用Celery进行异步任务处理
from celery import Celery

app = Celery('simulation', broker='redis://redis:6379/0')

@app.task
def process_simulation_task(task_id):
    """
    异步处理仿真任务

    优势:
    1. 解耦任务提交和执行
    2. 支持任务重试
    3. 可以水平扩展worker
    """
    task = get_task_by_id(task_id)

    # 执行仿真
    result = run_simulation(task.params)

    # 保存结果
    save_result(task_id, result)

    # 发送通知
    send_notification.delay(task.user_id, f"任务{task_id}完成")

# 提交任务
process_simulation_task.delay(task_id)
6.2 服务发现与注册
在动态伸缩的环境中,服务实例的地址会不断变化,需要服务发现机制。
# 使用Consul进行服务发现
import consul

class ServiceRegistry:
    """
    服务注册中心
    """
    def __init__(self, consul_host='localhost', consul_port=8500):
        self.consul = consul.Consul(host=consul_host, port=consul_port)

    def register_service(self, service_name, service_id, host, port, health_check_url):
        """注册服务"""
        self.consul.agent.service.register(
            name=service_name,
            service_id=service_id,
            address=host,
            port=port,
            check=consul.Check.http(
                health_check_url,
                interval='10s',
                timeout='5s'
            )
        )

    def discover_service(self, service_name):
        """发现服务实例"""
        _, services = self.consul.health.service(service_name)

        healthy_instances = []
        for service in services:
            checks = service['Checks']
            if all(check['Status'] == 'passing' for check in checks):
                healthy_instances.append({
                    'host': service['Service']['Address'],
                    'port': service['Service']['Port']
                })

        return healthy_instances

    def deregister_service(self, service_id):
        """注销服务"""
        self.consul.agent.service.deregister(service_id)
6.3 熔断与降级
在分布式系统中,需要防止故障扩散。
from circuitbreaker import circuit
import time

class CircuitBreakerConfig:
    """
    熔断器配置
    """
    FAILURE_THRESHOLD = 5       # 失败次数阈值
    RECOVERY_TIMEOUT = 60       # 恢复超时(秒)
    EXPECTED_EXCEPTION = Exception

@circuit(failure_threshold=CircuitBreakerConfig.FAILURE_THRESHOLD,
         recovery_timeout=CircuitBreakerConfig.RECOVERY_TIMEOUT,
         expected_exception=CircuitBreakerConfig.EXPECTED_EXCEPTION)
def call_external_service(service_url, data):
    """
    调用外部服务(带熔断保护)

    当失败次数超过阈值时,熔断器打开,
    后续请求直接返回错误,不再调用外部服务
    """
    response = requests.post(service_url, json=data, timeout=10)
    response.raise_for_status()
    return response.json()

# 降级策略
def fallback_strategy(task):
    """
    当主服务不可用时执行的降级策略
    """
    # 策略1:使用本地简化计算
    if task.task_type == 'heat':
        return run_simplified_heat_simulation(task.params)

    # 策略2:返回缓存结果
    cached_result = get_cached_result(task)
    if cached_result:
        return cached_result

    # 策略3:将任务标记为待处理,稍后重试
    queue_task_for_retry(task)
    return {'status': 'queued', 'message': '服务暂时不可用,任务已排队'}
REST API设计
7.1 API设计原则
7.1.1 RESTful设计规范
资源命名:
- 使用名词而非动词
- 使用复数形式
- 使用小写字母和连字符
✓ GET /api/v1/tasks              # 获取任务列表
✓ GET /api/v1/tasks/{id}         # 获取特定任务
✓ POST /api/v1/tasks             # 创建任务
✓ PUT /api/v1/tasks/{id}         # 更新任务
✓ DELETE /api/v1/tasks/{id}      # 删除任务
✗ GET /api/v1/getTask            # 错误:使用动词
✗ GET /api/v1/Task               # 错误:使用大写
HTTP状态码:
| 状态码 | 含义 | 使用场景 |
|---|---|---|
| 200 | OK | 请求成功 |
| 201 | Created | 资源创建成功 |
| 202 | Accepted | 请求已接受,异步处理中 |
| 400 | Bad Request | 请求参数错误 |
| 401 | Unauthorized | 未认证 |
| 403 | Forbidden | 无权限 |
| 404 | Not Found | 资源不存在 |
| 409 | Conflict | 资源冲突 |
| 422 | Unprocessable Entity | 验证错误 |
| 429 | Too Many Requests | 请求过于频繁 |
| 500 | Internal Server Error | 服务器内部错误 |
| 503 | Service Unavailable | 服务暂时不可用 |
7.1.2 API版本控制
/api/v1/tasks       # 版本1
/api/v2/tasks       # 版本2(可能有破坏性变更)
版本控制策略:
- URL路径版本(推荐):清晰明确
- Header版本:Accept: application/vnd.api.v1+json
- 查询参数版本:/api/tasks?version=1
7.2 云仿真API设计示例
7.2.1 任务管理API
# OpenAPI 3.0 规范
openapi: 3.0.0
info:
  title: Cloud Simulation API
  version: 1.0.0

paths:
  /api/v1/tasks:
    post:
      summary: 提交仿真任务
      requestBody:
        required: true
        content:
          application/json:
            schema:
              type: object
              required:
                - task_type
                - params
              properties:
                task_type:
                  type: string
                  enum: [heat, stress, fluid, modal]
                params:
                  type: object
                priority:
                  type: integer
                  minimum: 1
                  maximum: 10
                  default: 5
      responses:
        201:
          description: 任务创建成功
          content:
            application/json:
              schema:
                type: object
                properties:
                  task_id:
                    type: string
                  status:
                    type: string
                  estimated_time:
                    type: integer
                  queue_position:
                    type: integer

    get:
      summary: 获取任务列表
      parameters:
        - name: status
          in: query
          schema:
            type: string
            enum: [pending, running, completed, failed]
        - name: limit
          in: query
          schema:
            type: integer
            default: 20
        - name: offset
          in: query
          schema:
            type: integer
            default: 0
      responses:
        200:
          description: 任务列表
          content:
            application/json:
              schema:
                type: object
                properties:
                  total:
                    type: integer
                  tasks:
                    type: array
                    items:
                      $ref: '#/components/schemas/Task'

  /api/v1/tasks/{task_id}:
    get:
      summary: 获取任务详情
      parameters:
        - name: task_id
          in: path
          required: true
          schema:
            type: string
      responses:
        200:
          description: 任务详情
          content:
            application/json:
              schema:
                $ref: '#/components/schemas/Task'

    delete:
      summary: 取消任务
      responses:
        200:
          description: 任务已取消

  /api/v1/tasks/{task_id}/results:
    get:
      summary: 获取仿真结果
      parameters:
        - name: format
          in: query
          schema:
            type: string
            enum: [json, csv, vtk]
            default: json
      responses:
        200:
          description: 仿真结果
          content:
            application/json:
              schema:
                type: object
            text/csv:
              schema:
                type: string

components:
  schemas:
    Task:
      type: object
      properties:
        task_id:
          type: string
        task_type:
          type: string
        status:
          type: string
        priority:
          type: integer
        created_at:
          type: string
          format: date-time
        started_at:
          type: string
          format: date-time
        completed_at:
          type: string
          format: date-time
        progress:
          type: integer
          minimum: 0
          maximum: 100
7.2.2 Python客户端SDK
"""
云仿真平台Python客户端SDK

使用示例:
    from cloud_simulation import CloudSimulationClient

    client = CloudSimulationClient(
        base_url='https://api.simcloud.com',
        api_key='your-api-key'
    )

    # 提交任务
    task = client.submit_task(
        task_type='heat',
        params={'mesh_size': 200, 'iterations': 1000},
        priority=3
    )

    # 等待完成并获取结果
    result = client.wait_for_completion(task['task_id'])
"""

import requests
import time
from typing import Dict, List, Optional

class CloudSimulationClient:
    """
    云仿真平台客户端
    """

    def __init__(self, base_url: str, api_key: str, timeout: int = 30):
        """
        初始化客户端

        参数:
            base_url: API基础URL
            api_key: API密钥
            timeout: 请求超时时间(秒)
        """
        self.base_url = base_url.rstrip('/')
        self.api_key = api_key
        self.timeout = timeout
        self.session = requests.Session()
        self.session.headers.update({
            'Authorization': f'Bearer {api_key}',
            'Content-Type': 'application/json'
        })

    def submit_task(self, task_type: str, params: Dict,
                   priority: int = 5) -> Dict:
        """
        提交仿真任务

        参数:
            task_type: 任务类型 ('heat', 'stress', 'fluid', 'modal')
            params: 仿真参数
            priority: 优先级 (1-10, 1最高)

        返回:
            任务信息字典
        """
        data = {
            'task_type': task_type,
            'params': params,
            'priority': priority
        }

        response = self.session.post(
            f'{self.base_url}/api/v1/tasks',
            json=data,
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()

    def get_task(self, task_id: str) -> Dict:
        """
        获取任务详情

        参数:
            task_id: 任务ID

        返回:
            任务详情字典
        """
        response = self.session.get(
            f'{self.base_url}/api/v1/tasks/{task_id}',
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()

    def list_tasks(self, status: Optional[str] = None,
                  limit: int = 20, offset: int = 0) -> Dict:
        """
        获取任务列表

        参数:
            status: 任务状态过滤
            limit: 返回数量限制
            offset: 分页偏移

        返回:
            任务列表字典
        """
        params = {'limit': limit, 'offset': offset}
        if status:
            params['status'] = status

        response = self.session.get(
            f'{self.base_url}/api/v1/tasks',
            params=params,
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()

    def cancel_task(self, task_id: str) -> Dict:
        """
        取消任务

        参数:
            task_id: 任务ID

        返回:
            操作结果字典
        """
        response = self.session.delete(
            f'{self.base_url}/api/v1/tasks/{task_id}',
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()

    def get_result(self, task_id: str, format: str = 'json') -> Dict:
        """
        获取仿真结果

        参数:
            task_id: 任务ID
            format: 结果格式 ('json', 'csv', 'vtk')

        返回:
            仿真结果字典
        """
        response = self.session.get(
            f'{self.base_url}/api/v1/tasks/{task_id}/results',
            params={'format': format},
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()

    def wait_for_completion(self, task_id: str,
                           poll_interval: int = 5,
                           timeout: int = 3600) -> Dict:
        """
        等待任务完成

        参数:
            task_id: 任务ID
            poll_interval: 轮询间隔(秒)
            timeout: 最大等待时间(秒)

        返回:
            任务结果字典

        异常:
            TimeoutError: 等待超时
        """
        start_time = time.time()

        while time.time() - start_time < timeout:
            task = self.get_task(task_id)
            status = task['status']

            print(f"任务状态: {status}, 进度: {task.get('progress', 0)}%")

            if status == 'completed':
                return self.get_result(task_id)
            elif status == 'failed':
                raise RuntimeError(f"任务执行失败: {task.get('error_message')}")
            elif status == 'cancelled':
                raise RuntimeError("任务已被取消")

            time.sleep(poll_interval)

        raise TimeoutError(f"等待任务完成超时({timeout}秒)")

    def get_resource_status(self) -> Dict:
        """
        获取平台资源状态

        返回:
            资源状态字典
        """
        response = self.session.get(
            f'{self.base_url}/api/v1/resources',
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()


# 使用示例
if __name__ == '__main__':
    # 初始化客户端
    client = CloudSimulationClient(
        base_url='https://api.simcloud.com',
        api_key='your-api-key-here'
    )

    # 提交热传导仿真任务
    print("提交仿真任务...")
    task = client.submit_task(
        task_type='heat',
        params={
            'mesh_size': 200,
            'iterations': 1000,
            'alpha': 0.01
        },
        priority=3
    )

    print(f"任务已提交: {task['task_id']}")

    # 等待完成并获取结果
    try:
        result = client.wait_for_completion(task['task_id'])
        print(f"仿真完成!结果: {result}")
    except TimeoutError:
        print("等待超时")
    except RuntimeError as e:
        print(f"执行失败: {e}")
成本分析与优化
8.1 云仿真成本构成
云仿真的成本主要包括以下几个部分:
8.1.1 计算成本
计算成本是云仿真的主要支出,通常按使用时间和资源配置计费。
实例类型与价格(参考AWS/Azure/阿里云):
| 实例类型 | 配置 | 按需价格($/小时) | 适用场景 |
|---|---|---|---|
| 通用型 | 4核16GB | $0.20-$0.40 | 开发测试 |
| 计算优化型 | 16核32GB | $0.80-$1.60 | 中等规模仿真 |
| 内存优化型 | 32核256GB | $2.00-$4.00 | 大规模仿真 |
| GPU实例 | V100/A100 | $3.00-$10.00 | GPU加速仿真 |
计费模式选择:
-
按需实例(On-Demand)
- 灵活性最高,按小时计费
- 适合短期、不可预测的工作负载
- 价格最高
-
预留实例(Reserved)
- 预付费用,长期使用(1-3年)
- 相比按需可节省40%-60%
- 适合稳定的工作负载
-
Spot实例
- 利用云服务商的闲置资源
- 价格最低(按需的10%-50%)
- 但可能被中断,适合容错性好的任务
8.1.2 存储成本
| 存储类型 | 价格($/GB/月) | 特点 | 适用场景 |
|---|---|---|---|
| 对象存储 | $0.01-$0.02 | 高可靠、低成本 | 结果文件长期存储 |
| 块存储(SSD) | $0.10-$0.20 | 高性能、低延迟 | 运行时数据 |
| 归档存储 | $0.001-$0.005 | 极低价格、取回慢 | 历史数据归档 |
存储优化策略:
- 热数据(频繁访问):SSD存储
- 温数据(偶尔访问):对象存储
- 冷数据(很少访问):归档存储
- 自动生命周期管理:数据自动在不同存储层级间迁移
8.1.3 网络成本
- 入站流量:通常免费
- 出站流量:$0.05-$0.15/GB
- 跨区域传输:$0.01-$0.10/GB
网络优化策略:
- 将计算和数据放在同一区域
- 使用CDN加速结果下载
- 压缩传输数据
8.1.4 软件许可成本
| 软件类型 | 许可模式 | 年度成本 |
|---|---|---|
| 商业CAE软件 | 按核/按用户 | $10,000-$100,000 |
| 开源软件 | 免费 | $0 |
| 云原生许可 | 按使用量 | 按需付费 |
8.2 成本优化策略
8.2.1 资源选型优化
class CostOptimizer:
    """
    云仿真成本优化器
    """

    def __init__(self):
        self.instance_pricing = {
            'general': {'on_demand': 0.30, 'reserved': 0.18, 'spot': 0.10},
            'compute': {'on_demand': 0.80, 'reserved': 0.48, 'spot': 0.25},
            'memory': {'on_demand': 2.00, 'reserved': 1.20, 'spot': 0.60}
        }

    def recommend_instance_type(self, task_requirements):
        """
        根据任务需求推荐最优实例类型

        策略:
        1. 分析任务的CPU/内存/IO需求
        2. 选择满足需求的最小实例
        3. 考虑价格性能比
        """
        cpu_needed = task_requirements['cpu_cores']
        memory_needed = task_requirements['memory_gb']
        duration_hours = task_requirements['duration_hours']
        interruptible = task_requirements.get('interruptible', False)

        # 实例规格
        instance_types = [
            {'name': 'general', 'cpu': 4, 'memory': 16, 'price_tier': 'low'},
            {'name': 'compute', 'cpu': 16, 'memory': 32, 'price_tier': 'medium'},
            {'name': 'memory', 'cpu': 32, 'memory': 256, 'price_tier': 'high'}
        ]

        # 筛选满足需求的实例
        suitable_instances = [
            inst for inst in instance_types
            if inst['cpu'] >= cpu_needed and inst['memory'] >= memory_needed
        ]

        if not suitable_instances:
            return None, "无满足需求的实例类型"

        # 选择成本最低的
        best_instance = None
        min_cost = float('inf')

        for inst in suitable_instances:
            # 选择计费模式
            if interruptible:
                billing_mode = 'spot'
            elif duration_hours > 720:  # 超过一个月
                billing_mode = 'reserved'
            else:
                billing_mode = 'on_demand'

            hourly_rate = self.instance_pricing[inst['name']][billing_mode]
            total_cost = hourly_rate * duration_hours

            if total_cost < min_cost:
                min_cost = total_cost
                best_instance = {
                    'type': inst['name'],
                    'billing_mode': billing_mode,
                    'hourly_rate': hourly_rate,
                    'estimated_cost': total_cost
                }

        return best_instance, f"推荐实例: {best_instance['type']}, 预估成本: ${min_cost:.2f}"

    def optimize_storage_tier(self, data_access_pattern):
        """
        根据数据访问模式优化存储层级
        """
        access_frequency = data_access_pattern['frequency']  # daily/weekly/monthly
        data_size_gb = data_access_pattern['size_gb']
        retention_days = data_access_pattern['retention_days']

        # 存储价格($/GB/月)
        storage_pricing = {
            'ssd': 0.15,
            'object': 0.02,
            'archive': 0.005
        }

        # 根据访问频率推荐存储类型
        if access_frequency == 'daily':
            recommended_tier = 'ssd'
        elif access_frequency == 'weekly':
            recommended_tier = 'object'
        else:
            recommended_tier = 'archive'

        monthly_cost = storage_pricing[recommended_tier] * data_size_gb

        return {
            'recommended_tier': recommended_tier,
            'monthly_cost': monthly_cost,
            'annual_cost': monthly_cost * 12
        }
8.2.2 自动伸缩优化
通过自动伸缩避免资源浪费:
class AutoScalingOptimizer:
    """
    自动伸缩成本优化器
    """

    def __init__(self):
        self.min_nodes = 2      # 最小节点数(保证可用性)
        self.max_nodes = 50     # 最大节点数(成本控制)
        self.target_utilization = 0.7  # 目标利用率

    def calculate_optimal_nodes(self, current_metrics):
        """
        计算最优节点数量

        公式:
        optimal_nodes = current_tasks / (target_utilization * tasks_per_node)
        """
        current_tasks = current_metrics['running_tasks']
        queue_length = current_metrics['queue_length']
        current_nodes = current_metrics['total_nodes']
        avg_tasks_per_node = current_metrics.get('avg_tasks_per_node', 5)

        total_workload = current_tasks + queue_length

        # 计算需要的节点数
        needed_nodes = int(
            total_workload / (self.target_utilization * avg_tasks_per_node)
        )

        # 限制在最小和最大之间
        optimal_nodes = max(self.min_nodes, min(needed_nodes, self.max_nodes))

        # 计算成本节省
        if optimal_nodes < current_nodes:
            hourly_savings = (current_nodes - optimal_nodes) * 0.50  # $0.50/节点/小时
            return {
                'action': 'scale_down',
                'current_nodes': current_nodes,
                'optimal_nodes': optimal_nodes,
                'hourly_savings': hourly_savings,
                'monthly_savings': hourly_savings * 24 * 30
            }
        elif optimal_nodes > current_nodes:
            return {
                'action': 'scale_up',
                'current_nodes': current_nodes,
                'optimal_nodes': optimal_nodes,
                'reason': '工作负载增加'
            }

        return {'action': 'maintain', 'current_nodes': current_nodes}
8.2.3 混合云成本优化
class HybridCloudOptimizer:
    """
    混合云成本优化器

    策略:
    - 敏感数据/核心算法:私有云
    - 大规模计算/突发负载:公有云
    """

    def __init__(self):
        self.private_cloud_cost = 0.05  # $/核/小时(折旧后)
        self.public_cloud_cost = 0.20   # $/核/小时(按需)

    def optimize_workload_distribution(self, tasks):
        """
        优化工作负载在私有云和公有云之间的分布
        """
        private_cloud_capacity = 100  # 私有云最大容量(核)

        private_tasks = []
        public_tasks = []

        for task in tasks:
            # 敏感任务优先私有云
            if task.get('sensitive', False):
                if self._can_fit_in_private(task, private_tasks, private_cloud_capacity):
                    private_tasks.append(task)
                else:
                    # 私有云已满,使用公有云
                    public_tasks.append(task)
            else:
                # 非敏感任务,比较成本
                private_cost = self._calculate_private_cost(task)
                public_cost = self._calculate_public_cost(task)

                if private_cost < public_cost and \
                   self._can_fit_in_private(task, private_tasks, private_cloud_capacity):
                    private_tasks.append(task)
                else:
                    public_tasks.append(task)

        return {
            'private_cloud': private_tasks,
            'public_cloud': public_tasks,
            'total_cost': (
                sum(self._calculate_private_cost(t) for t in private_tasks) +
                sum(self._calculate_public_cost(t) for t in public_tasks)
            )
        }
8.3 成本监控与告警
class CostMonitor:
    """
    云仿真成本监控器
    """

    def __init__(self, budget_limit):
        self.budget_limit = budget_limit  # 月度预算上限
        self.daily_spend = []
        self.alerts = []

    def record_spend(self, amount, category):
        """记录支出"""
        today = datetime.now().date()

        # 查找今天的记录
        for record in self.daily_spend:
            if record['date'] == today:
                record['amount'] += amount
                record['categories'][category] = \
                    record['categories'].get(category, 0) + amount
                break
        else:
            self.daily_spend.append({
                'date': today,
                'amount': amount,
                'categories': {category: amount}
            })

    def check_budget(self):
        """检查预算使用情况"""
        # 计算本月总支出
        current_month = datetime.now().month
        monthly_spend = sum(
            record['amount'] for record in self.daily_spend
            if record['date'].month == current_month
        )

        # 计算预算使用率
        budget_usage = monthly_spend / self.budget_limit

        alerts = []

        if budget_usage >= 1.0:
            alerts.append({
                'level': 'critical',
                'message': f'预算已超支!已使用 ${monthly_spend:.2f} / ${self.budget_limit:.2f}'
            })
        elif budget_usage >= 0.9:
            alerts.append({
                'level': 'warning',
                'message': f'预算即将用尽!已使用 {budget_usage*100:.1f}%'
            })
        elif budget_usage >= 0.75:
            alerts.append({
                'level': 'info',
                'message': f'预算使用超过75%,已使用 ${monthly_spend:.2f}'
            })

        return {
            'monthly_spend': monthly_spend,
            'budget_usage': budget_usage,
            'remaining_budget': self.budget_limit - monthly_spend,
            'alerts': alerts
        }

    def forecast_monthly_cost(self):
        """预测月度总成本"""
        if not self.daily_spend:
            return 0

        # 基于过去7天的平均日支出预测
        recent_days = self.daily_spend[-7:]
        avg_daily_spend = sum(r['amount'] for r in recent_days) / len(recent_days)

        days_in_month = 30
        forecast = avg_daily_spend * days_in_month

        return forecast
Python代码实现详解
9.1 核心类解析
9.1.1 SimulationTask类
SimulationTask类是云仿真平台的核心数据模型,代表一个仿真任务。
class SimulationTask:
    """
    仿真任务类

    职责:
    1. 存储任务的所有元数据
    2. 估算资源需求
    3. 跟踪任务生命周期
    """

    def __init__(self, task_type, params, priority=5):
        """
        初始化仿真任务

        参数:
            task_type: 任务类型 ('heat', 'stress', 'fluid', 'modal')
            params: 仿真参数字典
            priority: 优先级 (1-10, 1最高)
        """
        # 任务标识
        self.task_id = str(uuid.uuid4())[:8]  # 生成唯一ID
        self.task_type = task_type
        self.params = params
        self.priority = priority
        self.status = TaskStatus.PENDING

        # 时间戳
        self.created_at = datetime.now()
        self.started_at = None
        self.completed_at = None

        # 资源需求估算(基于启发式规则)
        self.estimated_cpu = self._estimate_cpu()
        self.estimated_memory = self._estimate_memory()
        self.estimated_time = self._estimate_time()

        # 实际资源使用(执行后填充)
        self.actual_cpu = 0
        self.actual_memory = 0
        self.actual_time = 0

    def _estimate_cpu(self):
        """
        估算CPU需求

        策略:
        - 基础需求根据任务类型确定
        - 网格越大,需要的CPU越多
        """
        base_cpu = {'heat': 2, 'stress': 4, 'fluid': 8, 'modal': 2}
        mesh_size = self.params.get('mesh_size', 100)
        # 网格增大时,CPU需求线性增长
        return base_cpu.get(self.task_type, 2) * (mesh_size / 100)

    def _estimate_memory(self):
        """
        估算内存需求

        策略:
        - 内存需求与网格大小的平方成正比
        - 因为需要存储整个网格的数据
        """
        base_mem = {'heat': 1, 'stress': 2, 'fluid': 4, 'modal': 1}
        mesh_size = self.params.get('mesh_size', 100)
        # 网格增大时,内存需求平方增长
        return base_mem.get(self.task_type, 1) * (mesh_size / 100) ** 2
9.1.2 ComputeNode类
ComputeNode类代表云仿真平台中的一个计算节点。
class ComputeNode:
    """
    计算节点类

    职责:
    1. 管理节点的资源状态
    2. 分配和释放任务
    3. 跟踪节点健康状态
    """

    def __init__(self, node_id, cpu_cores, memory_gb, node_type='standard'):
        self.node_id = node_id
        self.cpu_cores = cpu_cores
        self.memory_gb = memory_gb
        self.node_type = node_type

        # 资源状态(动态变化)
        self.available_cpu = cpu_cores
        self.available_memory = memory_gb

        # 任务管理
        self.running_tasks = []
        self.completed_tasks = []

        # 节点状态
        self.status = 'online'
        self.last_heartbeat = datetime.now()

    def can_accept_task(self, task):
        """
        检查节点是否可以接受任务

        条件:
        1. 有足够的CPU资源
        2. 有足够的内存资源
        3. 节点在线
        """
        return (
            self.available_cpu >= task.estimated_cpu and
            self.available_memory >= task.estimated_memory and
            self.status == 'online'
        )

    def assign_task(self, task):
        """
        将任务分配给节点

        操作:
        1. 预留资源
        2. 更新任务状态
        3. 记录开始时间
        """
        if self.can_accept_task(task):
            # 预留资源
            self.available_cpu -= task.estimated_cpu
            self.available_memory -= task.estimated_memory

            # 更新任务
            self.running_tasks.append(task)
            task.status = TaskStatus.RUNNING
            task.started_at = datetime.now()

            return True
        return False
9.1.3 TaskScheduler类
TaskScheduler类负责任务的调度和队列管理。
class TaskScheduler:
    """
    任务调度器

    支持多种调度策略:
    - priority: 优先级调度
    - fifo: 先来先服务
    - fair: 公平调度
    """

    def __init__(self, scheduling_policy='priority'):
        self.scheduling_policy = scheduling_policy
        self.task_queue = []  # 等待队列
        self.running_tasks = []
        self.completed_tasks = []

    def submit_task(self, task):
        """
        提交任务到队列

        流程:
        1. 更新任务状态为QUEUED
        2. 加入队列
        3. 根据策略排序队列
        """
        task.status = TaskStatus.QUEUED
        self.task_queue.append(task)
        self._sort_queue()
        return task.task_id

    def _sort_queue(self):
        """
        根据调度策略排序队列

        priority策略:
        - 首先按优先级排序(数字小的优先)
        - 相同优先级按提交时间排序
        """
        if self.scheduling_policy == 'priority':
            self.task_queue.sort(key=lambda t: (t.priority, t.created_at))
        elif self.scheduling_policy == 'fifo':
            self.task_queue.sort(key=lambda t: t.created_at)
        elif self.scheduling_policy == 'fair':
            self.task_queue.sort(key=lambda t: (t.estimated_time, t.priority))

    def schedule_tasks(self, compute_nodes):
        """
        将队列中的任务调度到计算节点

        算法:
        1. 遍历等待队列
        2. 为每个任务找到合适的节点
        3. 分配任务并更新资源状态
        """
        scheduled = []

        for task in self.task_queue[:]:
            # 找到能满足资源需求且剩余资源最少的节点(Best Fit)
            best_node = None
            min_remaining = float('inf')

            for node in compute_nodes:
                if node.can_accept(task):
                    remaining = node.available_cpu - task.estimated_cpu
                    if 0 <= remaining < min_remaining:
                        min_remaining = remaining
                        best_node = node

            if best_node:
                best_node.assign_task(task)
                self.task_queue.remove(task)
                self.running_tasks.append(task)
                scheduled.append((task, best_node))

        return scheduled
9.1.4 CloudSimulationPlatform类
CloudSimulationPlatform类是整个云仿真平台的入口,负责协调各个组件。
class CloudSimulationPlatform:
    """
    云仿真平台主类

    职责:
    1. 管理计算节点池
    2. 协调任务调度
    3. 提供平台级统计信息
    4. 支持弹性伸缩
    """

    def __init__(self):
        """初始化云仿真平台"""
        self.compute_nodes = []
        self.scheduler = TaskScheduler()
        self.all_tasks = {}

        print("="*60)
        print("云仿真平台初始化")
        print("="*60)

    def add_compute_node(self, cpu_cores, memory_gb, node_type='standard'):
        """
        添加计算节点

        参数:
            cpu_cores: CPU核心数
            memory_gb: 内存大小(GB)
            node_type: 节点类型
        """
        node_id = f"node_{len(self.compute_nodes)+1}"
        node = ComputeNode(node_id, cpu_cores, memory_gb, node_type)
        self.compute_nodes.append(node)
        print(f"添加计算节点: {node_id} ({cpu_cores}核, {memory_gb}GB)")
        return node_id

    def submit_task(self, task_type, params, priority=5):
        """
        提交仿真任务

        流程:
        1. 创建任务对象
        2. 提交到调度器
        3. 尝试立即调度
        """
        task = SimulationTask(task_type, params, priority)
        self.scheduler.submit_task(task)
        self.all_tasks[task.task_id] = task

        # 尝试调度
        self.scheduler.schedule_tasks(self.compute_nodes)

        return task

    def get_platform_stats(self):
        """
        获取平台统计信息

        返回:
            包含资源使用、任务状态等信息的字典
        """
        total_cpu = sum(node.cpu_cores for node in self.compute_nodes)
        total_memory = sum(node.memory_gb for node in self.compute_nodes)

        available_cpu = sum(node.available_cpu for node in self.compute_nodes)
        available_memory = sum(node.available_memory for node in self.compute_nodes)

        return {
            'total_nodes': len(self.compute_nodes),
            'total_cpu': total_cpu,
            'total_memory': total_memory,
            'available_cpu': available_cpu,
            'available_memory': available_memory,
            'cpu_utilization': (total_cpu - available_cpu) / total_cpu if total_cpu > 0 else 0,
            'memory_utilization': (total_memory - available_memory) / total_memory if total_memory > 0 else 0,
            **self.scheduler.get_queue_stats()
        }
案例实战
10.1 案例一:基础云仿真平台搭建
场景描述:搭建一个基础的云仿真平台,模拟提交多个热传导仿真任务,观察任务调度和执行过程。
学习目标:
- 理解云仿真平台的基本工作流程
- 掌握任务提交和资源分配机制
- 学会查看平台状态统计
"""
案例一:基础云仿真平台
"""
import matplotlib.pyplot as plt
import numpy as np
from datetime import datetime

def example_basic_cloud_simulation():
    """基础云仿真平台示例"""
    print("\n" + "="*60)
    print("案例一:基础云仿真平台")
    print("="*60)

    # 创建平台
    platform = CloudSimulationPlatform()

    # 添加计算节点
    platform.add_compute_node(8, 32, 'standard')
    platform.add_compute_node(16, 64, 'high_memory')
    platform.add_compute_node(8, 32, 'standard')

    # 提交不同类型的仿真任务
    tasks = [
        ('heat', {'mesh_size': 100, 'iterations': 500}, 2),
        ('stress', {'mesh_size': 150, 'iterations': 800}, 1),
        ('fluid', {'mesh_size': 80, 'iterations': 300}, 3),
        ('modal', {'mesh_size': 200, 'iterations': 1000}, 2),
        ('heat', {'mesh_size': 120, 'iterations': 600}, 4),
    ]

    print("\n提交仿真任务...")
    submitted_tasks = []
    for task_type, params, priority in tasks:
        task = platform.submit_task(task_type, params, priority)
        submitted_tasks.append(task)
        print(f"  任务 {task.task_id}: {task_type}, "
              f"优先级={priority}, "
              f"预估CPU={task.estimated_cpu:.1f}, "
              f"预估内存={task.estimated_memory:.1f}GB")

    # 查看平台状态
    print("\n平台状态:")
    stats = platform.get_platform_stats()
    for key, value in stats.items():
        if isinstance(value, float):
            print(f"  {key}: {value:.2f}")
        else:
            print(f"  {key}: {value}")

    return platform, submitted_tasks
运行结果分析:
- 观察任务如何根据优先级和资源需求被分配到不同节点
- 分析CPU和内存的利用率变化
- 理解Best Fit调度算法的实际效果
10.2 案例二:调度策略对比分析
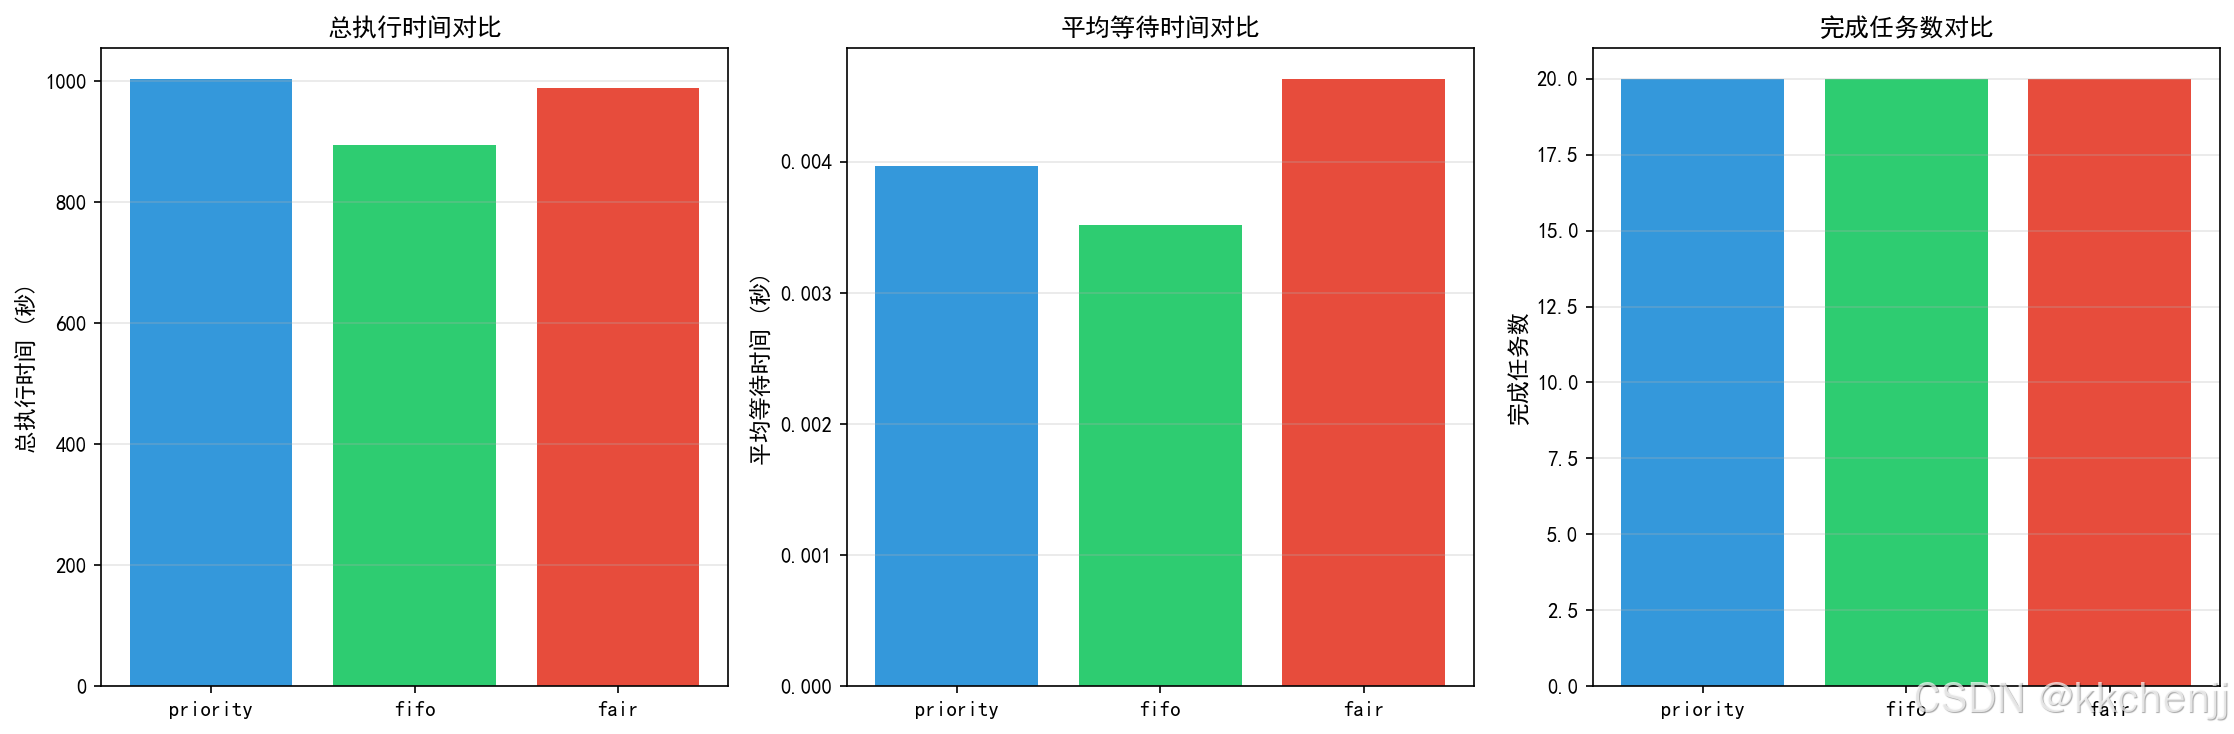
场景描述:比较不同调度策略(优先级、FIFO、公平调度)对任务执行效率的影响。
学习目标:
- 理解不同调度策略的特点
- 学会根据场景选择合适的调度策略
- 掌握调度性能评估方法
def example_scheduling_policies():
    """调度策略对比示例"""
    print("\n" + "="*60)
    print("案例二:调度策略对比")
    print("="*60)

    policies = ['priority', 'fifo', 'fair']
    results = {}

    for policy in policies:
        print(f"\n--- 测试策略: {policy} ---")

        # 创建平台
        platform = CloudSimulationPlatform()
        platform.scheduler.scheduling_policy = policy

        # 添加节点
        for _ in range(3):
            platform.add_compute_node(8, 32)

        # 提交相同的一批任务
        tasks_config = [
            ('heat', {'mesh_size': 100}, 1),
            ('heat', {'mesh_size': 100}, 5),
            ('heat', {'mesh_size': 100}, 3),
            ('heat', {'mesh_size': 100}, 1),
            ('heat', {'mesh_size': 100}, 5),
        ]

        for task_type, params, priority in tasks_config:
            platform.submit_task(task_type, params, priority)

        # 记录队列状态
        stats = platform.get_platform_stats()
        results[policy] = {
            'queue_length': stats.get('queue_length', 0),
            'running_tasks': stats.get('running_tasks', 0)
        }

        print(f"  等待队列长度: {results[policy]['queue_length']}")
        print(f"  运行中任务数: {results[policy]['running_tasks']}")

    # 可视化对比
    fig, axes = plt.subplots(1, 2, figsize=(12, 5))

    policies_list = list(results.keys())
    queue_lengths = [results[p]['queue_length'] for p in policies_list]
    running_tasks = [results[p]['running_tasks'] for p in policies_list]

    axes[0].bar(policies_list, queue_lengths, color=['#FF6B6B', '#4ECDC4', '#45B7D1'])
    axes[0].set_ylabel('等待队列长度')
    axes[0].set_title('不同策略的等待队列长度对比')

    axes[1].bar(policies_list, running_tasks, color=['#FF6B6B', '#4ECDC4', '#45B7D1'])
    axes[1].set_ylabel('运行中任务数')
    axes[1].set_title('不同策略的并发执行数对比')

    plt.tight_layout()
    plt.savefig('scheduling_policies_comparison.png', dpi=150)
    plt.close()

    print("\n可视化结果已保存")
    return results
策略选择建议:
- 优先级调度:适用于有明确紧急程度的任务,如VIP用户的仿真需求
- FIFO调度:适用于公平性要求高的场景,避免低优先级任务饥饿
- 公平调度:适用于资源受限且需要平衡各用户等待时间的场景
10.3 案例三:资源弹性伸缩模拟
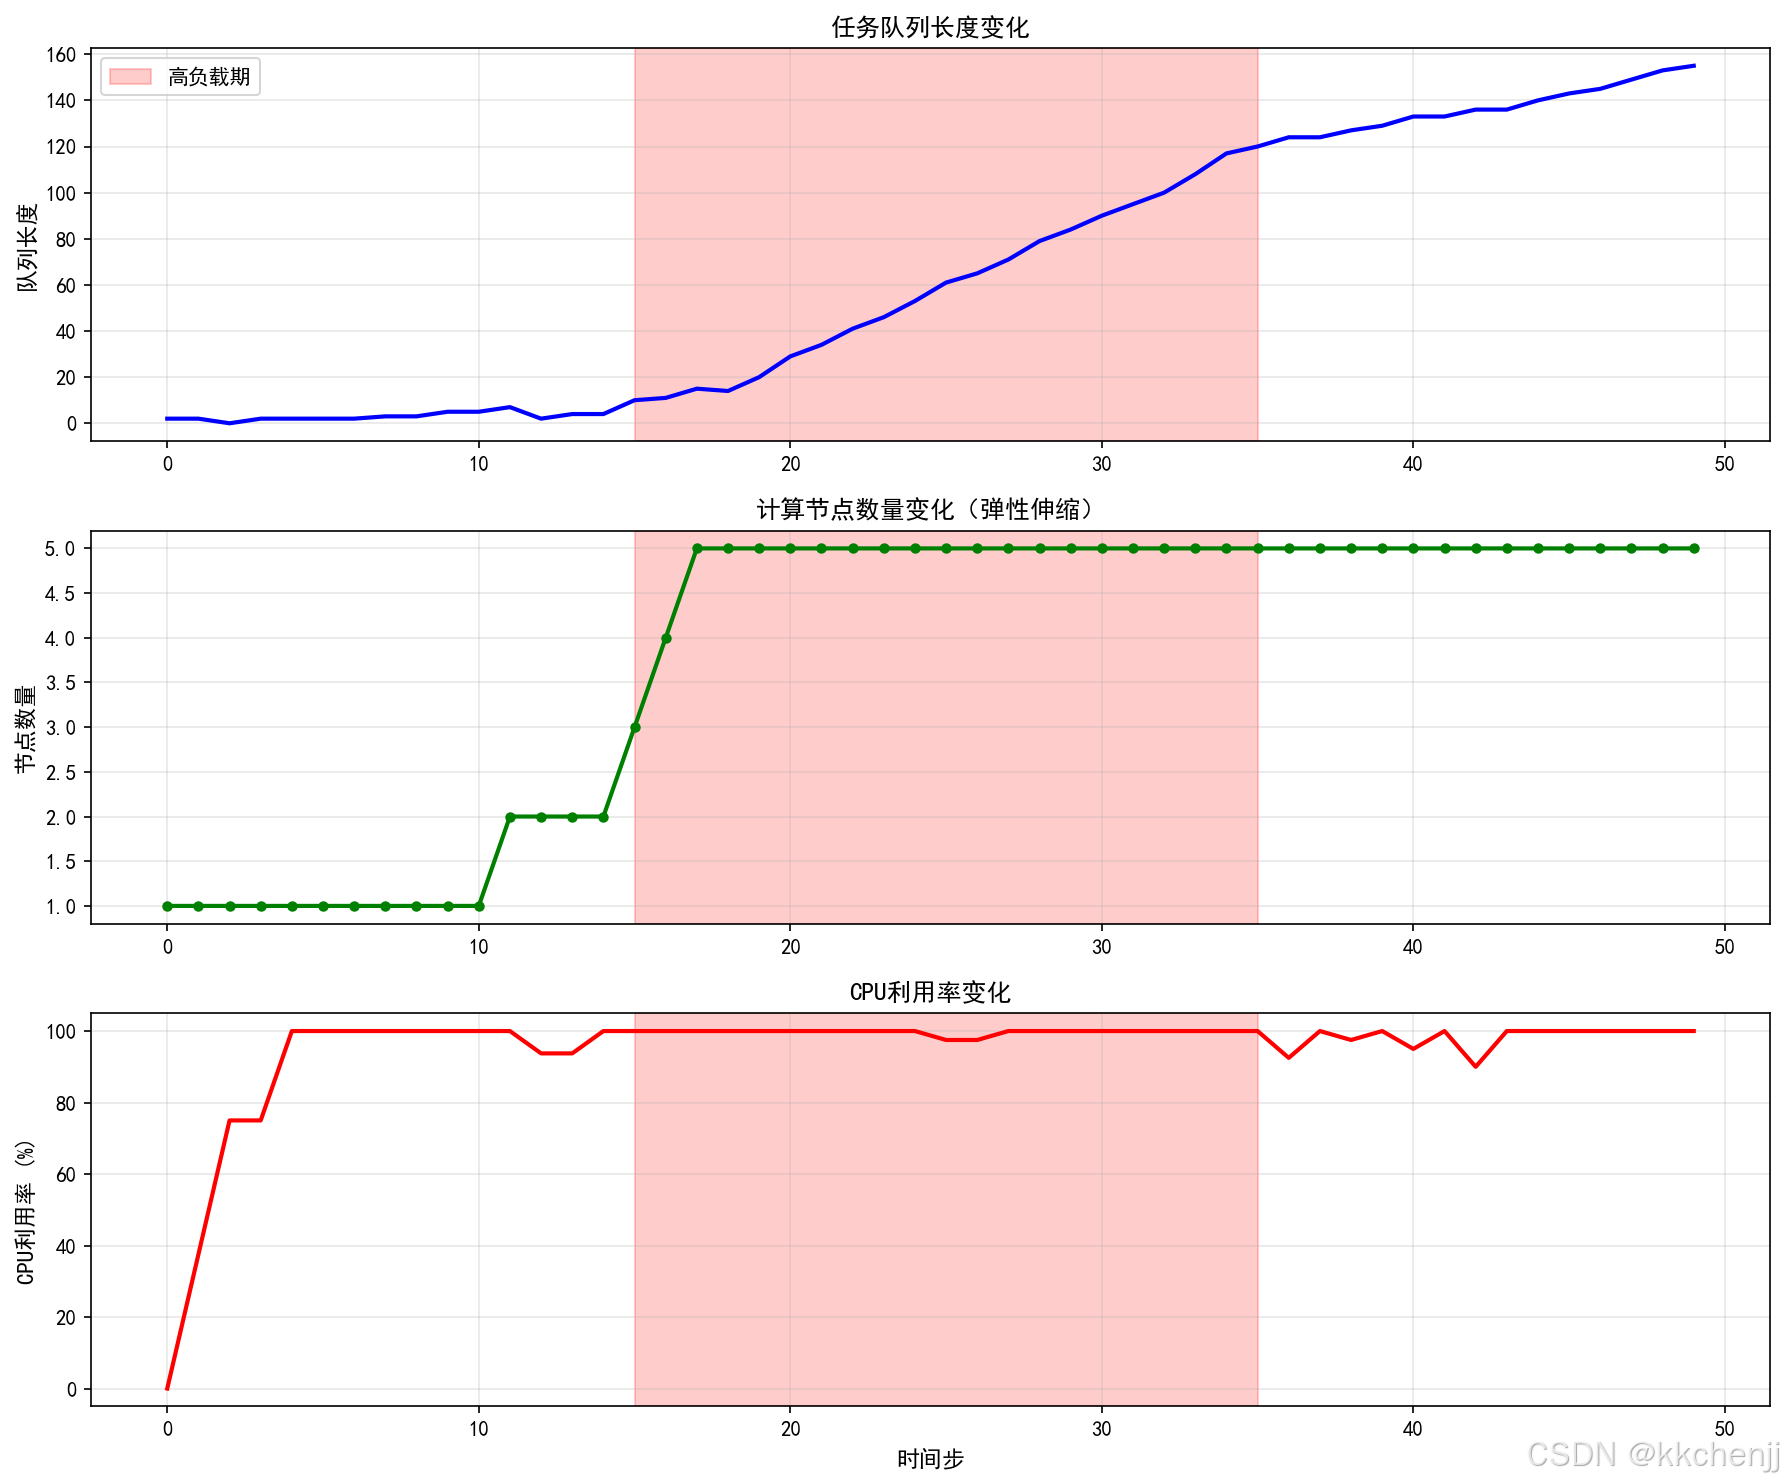
场景描述:模拟工作负载波动场景,观察自动伸缩策略如何动态调整计算节点数量。
学习目标:
- 理解弹性伸缩的工作原理
- 掌握基于阈值的伸缩策略
- 学会评估伸缩效果
def example_auto_scaling():
    """弹性伸缩示例"""
    print("\n" + "="*60)
    print("案例三:资源弹性伸缩")
    print("="*60)

    platform = CloudSimulationPlatform()
    scaler = ThresholdBasedAutoscaler()

    # 初始节点
    platform.add_compute_node(8, 32)
    platform.add_compute_node(8, 32)

    print("\n初始状态: 2个节点")

    # 模拟工作负载变化
    workload_scenarios = [
        {'name': '低负载', 'tasks': 2},
        {'name': '中负载', 'tasks': 8},
        {'name': '高负载', 'tasks': 20},
        {'name': '负载下降', 'tasks': 5},
    ]

    history = []

    for scenario in workload_scenarios:
        print(f"\n--- {scenario['name']} ---")

        # 提交任务
        for i in range(scenario['tasks']):
            platform.submit_task('heat', {'mesh_size': 100}, priority=5)

        # 获取指标
        stats = platform.get_platform_stats()
        metrics = {
            'avg_cpu_utilization': stats['cpu_utilization'],
            'queue_length': stats.get('queue_length', 0),
            'total_nodes': stats['total_nodes']
        }

        # 评估伸缩需求
        action = scaler.evaluate(metrics)
        print(f"  CPU利用率: {metrics['avg_cpu_utilization']:.2%}")
        print(f"  队列长度: {metrics['queue_length']}")
        print(f"  建议操作: {action}")

        # 执行伸缩
        if action == 'scale_up':
            platform.add_compute_node(8, 32)
            print(f"  -> 扩容完成,当前节点数: {len(platform.compute_nodes)}")
        elif action == 'scale_down' and len(platform.compute_nodes) > 2:
            platform.compute_nodes.pop()
            print(f"  -> 缩容完成,当前节点数: {len(platform.compute_nodes)}")

        history.append({
            'scenario': scenario['name'],
            'nodes': len(platform.compute_nodes),
            'cpu_util': metrics['avg_cpu_utilization'],
            'queue': metrics['queue_length']
        })

    # 可视化
    fig, axes = plt.subplots(2, 1, figsize=(10, 8))

    scenarios = [h['scenario'] for h in history]
    nodes = [h['nodes'] for h in history]
    cpu_utils = [h['cpu_util'] * 100 for h in history]

    axes[0].plot(scenarios, nodes, 'o-', linewidth=2, markersize=8, color='#45B7D1')
    axes[0].set_ylabel('节点数量')
    axes[0].set_title('弹性伸缩过程')
    axes[0].grid(True, alpha=0.3)

    axes[1].bar(scenarios, cpu_utils, color='#FF6B6B', alpha=0.7)
    axes[1].axhline(y=80, color='red', linestyle='--', label='扩容阈值')
    axes[1].axhline(y=20, color='green', linestyle='--', label='缩容阈值')
    axes[1].set_ylabel('CPU利用率 (%)')
    axes[1].set_title('CPU利用率变化')
    axes[1].legend()

    plt.tight_layout()
    plt.savefig('auto_scaling_simulation.png', dpi=150)
    plt.close()

    return history
伸缩策略优化建议:
- 设置合理的冷却时间,避免频繁伸缩
- 结合预测算法提前扩容,减少响应延迟
- 考虑成本因素,在性能和成本间取得平衡
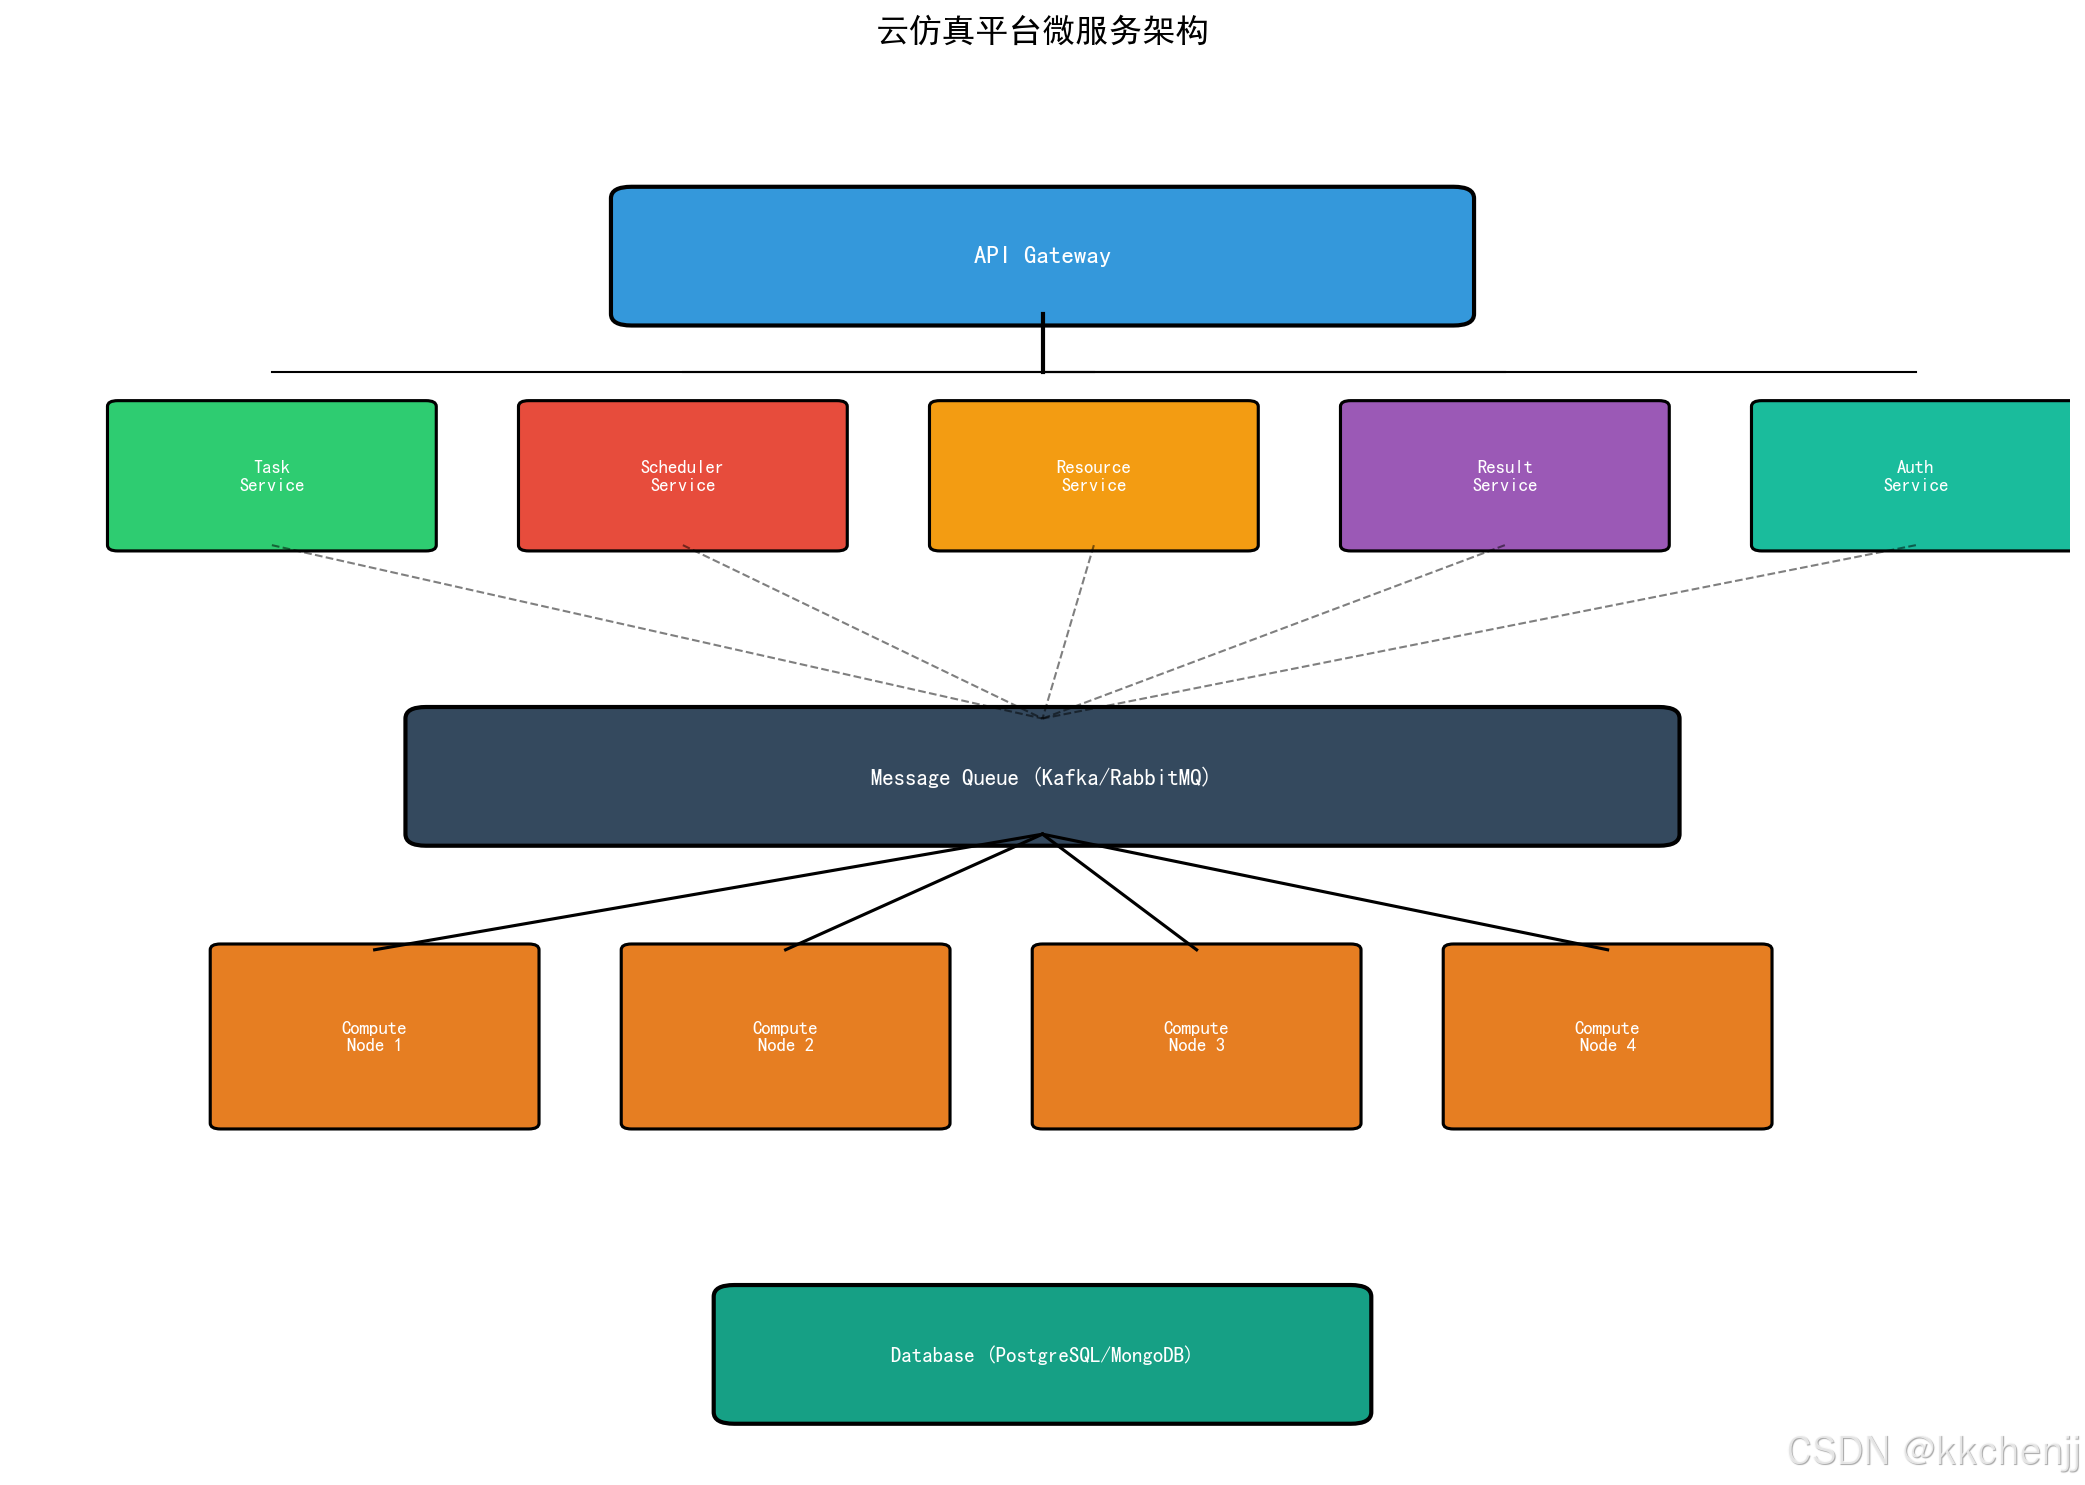
10.4 案例四:微服务架构可视化
场景描述:可视化展示云仿真平台的微服务架构及其通信关系。
学习目标:
- 理解微服务架构的组成
- 掌握服务间通信模式
- 学会设计分布式系统
def example_microservices_architecture():
    """微服务架构可视化示例"""
    print("\n" + "="*60)
    print("案例四:微服务架构")
    print("="*60)

    # 定义微服务
    services = {
        'API Gateway': {'type': 'gateway', 'layer': 0},
        'Task Service': {'type': 'service', 'layer': 1, 'dependencies': ['API Gateway']},
        'Scheduler Service': {'type': 'service', 'layer': 1, 'dependencies': ['API Gateway']},
        'Resource Service': {'type': 'service', 'layer': 1, 'dependencies': ['API Gateway']},
        'Result Service': {'type': 'service', 'layer': 1, 'dependencies': ['API Gateway']},
        'Auth Service': {'type': 'service', 'layer': 1, 'dependencies': ['API Gateway']},
        'Message Queue': {'type': 'middleware', 'layer': 2},
        'Compute Node 1': {'type': 'compute', 'layer': 3, 'dependencies': ['Scheduler Service']},
        'Compute Node 2': {'type': 'compute', 'layer': 3, 'dependencies': ['Scheduler Service']},
        'Compute Node 3': {'type': 'compute', 'layer': 3, 'dependencies': ['Scheduler Service']},
        'Object Storage': {'type': 'storage', 'layer': 3, 'dependencies': ['Result Service']},
        'Database': {'type': 'storage', 'layer': 3, 'dependencies': ['Task Service']},
    }

    # 创建可视化
    fig, ax = plt.subplots(figsize=(14, 10))
    ax.set_xlim(0, 10)
    ax.set_ylim(0, 10)
    ax.axis('off')

    # 颜色映射
    colors = {
        'gateway': '#FF6B6B',
        'service': '#4ECDC4',
        'middleware': '#FFE66D',
        'compute': '#95E1D3',
        'storage': '#F38181'
    }

    # 绘制层次背景
    layer_names = ['接入层', '服务层', '中间件层', '资源层']
    for i, name in enumerate(layer_names):
        y = 8.5 - i * 2
        ax.axhspan(y-0.8, y+0.8, alpha=0.1, color='gray')
        ax.text(0.3, y, name, fontsize=11, fontweight='bold', va='center')

    # 绘制服务节点
    positions = {}
    layer_counts = {0: 0, 1: 0, 2: 0, 3: 0}
    layer_positions = {0: [], 1: [], 2: [], 3: []}

    for name, info in services.items():
        layer = info['layer']
        layer_counts[layer] += 1

    for name, info in services.items():
        layer = info['layer']
        idx = len(layer_positions[layer])

        if layer == 0:
            x = 5
        else:
            spacing = 9 / (layer_counts[layer] + 1)
            x = spacing * (idx + 1)

        y = 8.5 - layer * 2
        positions[name] = (x, y)
        layer_positions[layer].append(name)

        # 绘制节点
        color = colors.get(info['type'], 'gray')
        circle = plt.Circle((x, y), 0.4, color=color, alpha=0.8)
        ax.add_patch(circle)

        # 添加标签
        ax.text(x, y, name.replace(' ', '\n'), ha='center', va='center',
                fontsize=8, fontweight='bold', color='white')

    # 绘制连接
    for name, info in services.items():
        if 'dependencies' in info:
            for dep in info['dependencies']:
                if dep in positions:
                    x1, y1 = positions[dep]
                    x2, y2 = positions[name]
                    ax.arrow(x1, y1-0.4, x2-x1, y2-y1+0.8,
                            head_width=0.1, head_length=0.1,
                            fc='gray', ec='gray', alpha=0.5,
                            length_includes_head=True)

    ax.set_title('云仿真平台微服务架构图', fontsize=16, fontweight='bold', pad=20)

    # 图例
    legend_elements = [plt.Rectangle((0,0),1,1, facecolor=c, label=t.title())
                      for t, c in colors.items()]
    ax.legend(handles=legend_elements, loc='upper right', fontsize=9)

    plt.tight_layout()
    plt.savefig('microservices_architecture.png', dpi=150, bbox_inches='tight')
    plt.close()

    print("微服务架构图已保存")
    return services
10.5 案例五:成本分析与优化
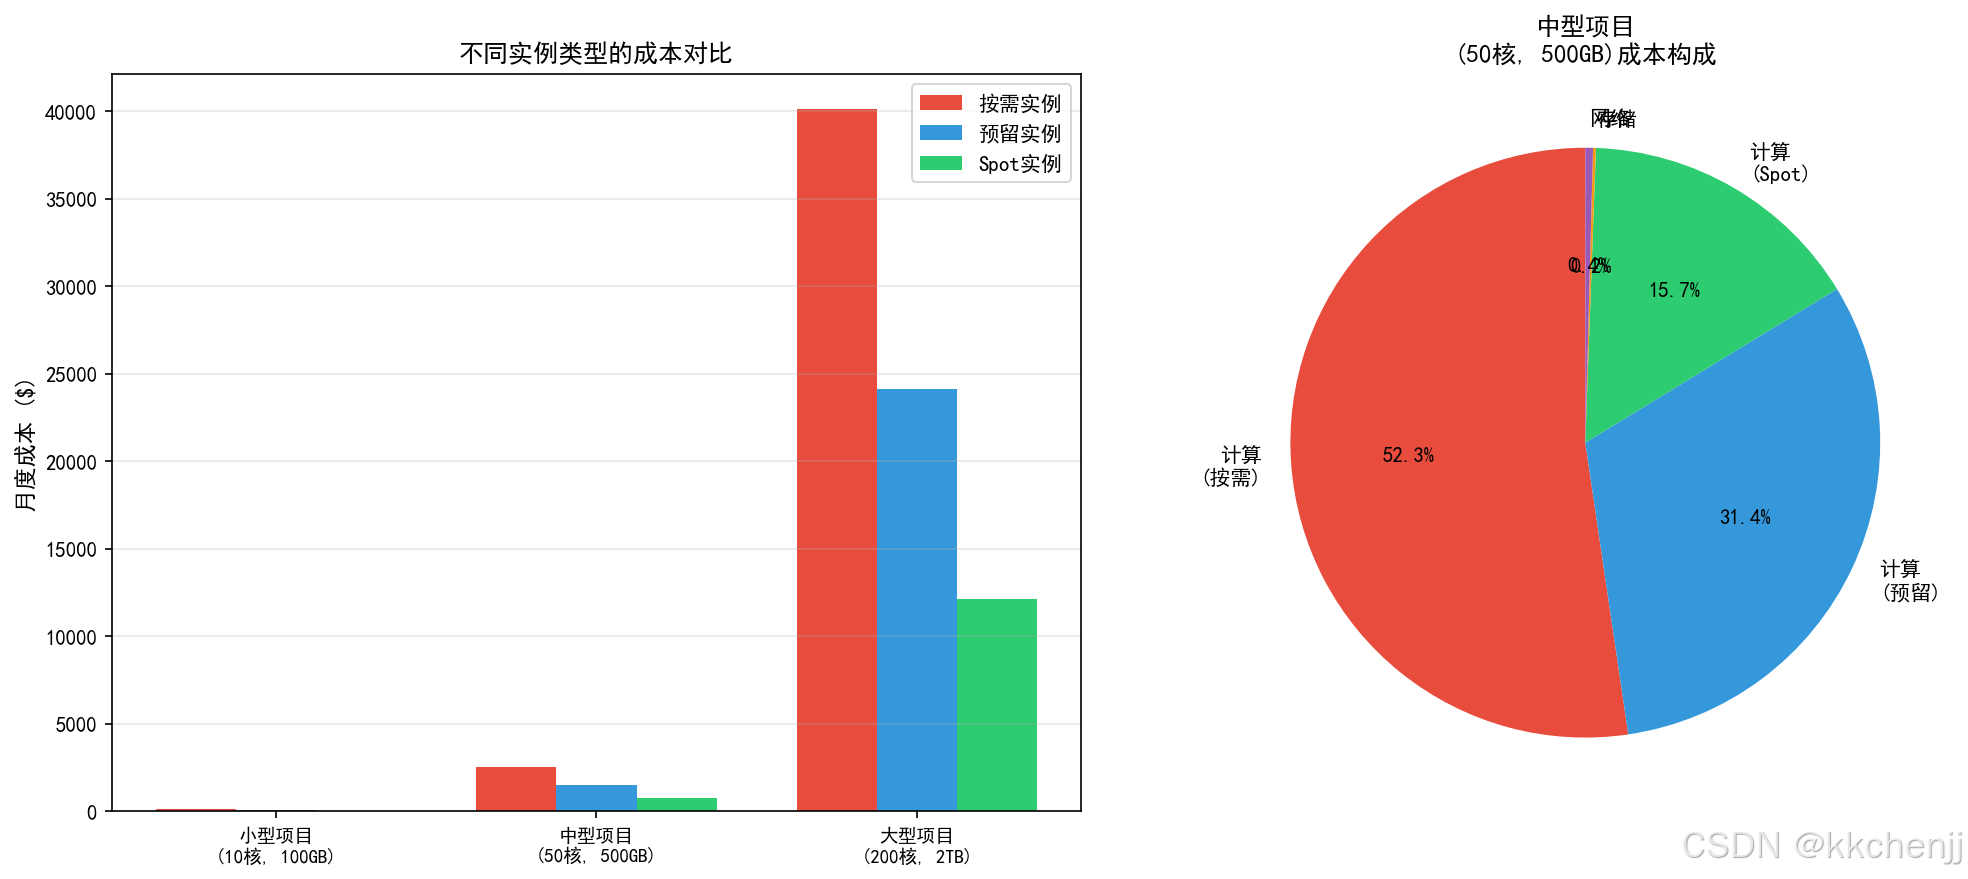
场景描述:分析不同资源配置方案的成本,找到性价比最优的配置。
学习目标:
- 掌握云仿真成本构成
- 学会成本估算和优化
- 理解不同计费模式的适用场景
def example_cost_analysis():
    """成本分析示例"""
    print("\n" + "="*60)
    print("案例五:成本分析与优化")
    print("="*60)

    optimizer = CostOptimizer()

    # 定义不同规模和类型的仿真任务
    task_scenarios = [
        {
            'name': '小规模热分析',
            'requirements': {
                'cpu_cores': 4,
                'memory_gb': 16,
                'duration_hours': 2,
                'interruptible': True
            }
        },
        {
            'name': '大规模应力分析',
            'requirements': {
                'cpu_cores': 32,
                'memory_gb': 128,
                'duration_hours': 24,
                'interruptible': False
            }
        },
        {
            'name': 'CFD流体仿真',
            'requirements': {
                'cpu_cores': 16,
                'memory_gb': 64,
                'duration_hours': 8,
                'interruptible': True
            }
        },
    ]

    print("\n任务成本分析:")
    results = []

    for scenario in task_scenarios:
        print(f"\n{scenario['name']}:")
        req = scenario['requirements']

        # 获取推荐配置
        recommendation, message = optimizer.recommend_instance_type(req)

        print(f"  资源需求: {req['cpu_cores']}核, {req['memory_gb']}GB, "
              f"{req['duration_hours']}小时")
        print(f"  {message}")

        if recommendation:
            results.append({
                'name': scenario['name'],
                'cost': recommendation['estimated_cost'],
                'type': recommendation['type'],
                'billing': recommendation['billing_mode']
            })

    # 可视化成本对比
    if results:
        fig, ax = plt.subplots(figsize=(10, 6))

        names = [r['name'] for r in results]
        costs = [r['cost'] for r in results]
        colors_bar = ['#4ECDC4', '#FF6B6B', '#FFE66D']

        bars = ax.barh(names, costs, color=colors_bar)

        # 添加数值标签
        for i, (bar, cost) in enumerate(zip(bars, costs)):
            ax.text(cost + 0.5, bar.get_y() + bar.get_height()/2,
                   f'${cost:.2f}', va='center', fontsize=10)

        ax.set_xlabel('预估成本 (USD)', fontsize=12)
        ax.set_title('不同仿真任务的成本估算', fontsize=14, fontweight='bold')
        ax.set_xlim(0, max(costs) * 1.2)

        plt.tight_layout()
        plt.savefig('cost_analysis.png', dpi=150)
        plt.close()

        print("\n成本分析图已保存")

    return results
成本优化最佳实践:
- 预留实例:对于长期稳定的工作负载,购买预留实例可节省40%-60%
- Spot实例:对于可中断的任务,使用Spot实例可节省70%-90%
- 自动伸缩:根据负载动态调整资源,避免资源浪费
- 存储分层:根据数据访问频率选择合适的存储类型
- 混合云策略:敏感数据本地处理,大规模计算上云
10.6 案例六:REST API设计与客户端SDK
场景描述:设计云仿真平台的REST API,并提供Python客户端SDK。
学习目标:
- 掌握REST API设计原则
- 学会构建API客户端
- 理解API认证和安全
"""
案例六:REST API客户端SDK

这是一个模拟的客户端SDK,展示如何与云仿真平台API交互
"""

class CloudSimulationClient:
    """
    云仿真平台Python客户端

    提供简洁的API来提交任务、查询状态和获取结果
    """

    def __init__(self, base_url: str, api_key: str, timeout: int = 30):
        """
        初始化客户端

        参数:
            base_url: API基础URL
            api_key: API密钥
            timeout: 请求超时时间(秒)
        """
        self.base_url = base_url.rstrip('/')
        self.api_key = api_key
        self.timeout = timeout

        # 创建会话,自动添加认证头
        self.session = requests.Session()
        self.session.headers.update({
            'Authorization': f'Bearer {api_key}',
            'Content-Type': 'application/json'
        })

    def submit_task(self, task_type: str, params: Dict,
                   priority: int = 5) -> Dict:
        """
        提交仿真任务

        参数:
            task_type: 任务类型 ('heat', 'stress', 'fluid', 'modal')
            params: 仿真参数
            priority: 优先级 (1-10, 1最高)

        返回:
            包含task_id的任务信息字典
        """
        payload = {
            'task_type': task_type,
            'params': params,
            'priority': priority
        }

        response = self.session.post(
            f'{self.base_url}/api/v1/tasks',
            json=payload,
            timeout=self.timeout
        )
        response.raise_for_status()

        return response.json()

    def get_task(self, task_id: str) -> Dict:
        """获取任务状态"""
        response = self.session.get(
            f'{self.base_url}/api/v1/tasks/{task_id}',
            timeout=self.timeout
        )
        response.raise_for_status()
        return response.json()

    def wait_for_completion(self, task_id: str,
                           poll_interval: int = 5,
                           timeout: int = 3600) -> Dict:
        """
        等待任务完成

        参数:
            task_id: 任务ID
            poll_interval: 轮询间隔(秒)
            timeout: 最大等待时间(秒)

        返回:
            任务结果字典

        异常:
            TimeoutError: 等待超时
        """
        start_time = time.time()

        while time.time() - start_time < timeout:
            task = self.get_task(task_id)
            status = task['status']

            print(f"任务状态: {status}, 进度: {task.get('progress', 0)}%")

            if status == 'completed':
                return self.get_result(task_id)
            elif status == 'failed':
                raise RuntimeError(f"任务执行失败: {task.get('error_message')}")
            elif status == 'cancelled':
                raise RuntimeError("任务已被取消")

            time.sleep(poll_interval)

        raise TimeoutError(f"等待任务完成超时({timeout}秒)")

# 使用示例
if __name__ == '__main__':
    # 初始化客户端
    client = CloudSimulationClient(
        base_url='https://api.simcloud.com',
        api_key='your-api-key-here'
    )

    # 提交热传导仿真任务
    print("提交仿真任务...")
    task = client.submit_task(
        task_type='heat',
        params={
            'mesh_size': 200,
            'iterations': 1000,
            'alpha': 0.01
        },
        priority=3
    )

    print(f"任务已提交: {task['task_id']}")

    # 等待完成并获取结果
    try:
        result = client.wait_for_completion(task['task_id'])
        print(f"仿真完成!结果: {result}")
    except TimeoutError:
        print("等待超时")
    except RuntimeError as e:
        print(f"执行失败: {e}")
总结与习题
11.1 知识点总结
通过本主题的学习,我们系统性地掌握了云仿真平台的构建原理和实现方法:
核心概念:
- 云计算服务模型(IaaS、PaaS、SaaS)的特点和适用场景
- 云部署模型(公有云、私有云、混合云、多云)的选择策略
- 容器化技术(Docker)和容器编排(Kubernetes)在云仿真中的应用
架构设计:
- 分层架构设计:接入层、网关层、服务层、消息层、计算层、存储层
- 微服务架构的优势和设计原则
- 服务间通信模式(同步REST/gRPC、异步消息队列)
关键技术:
- 任务调度算法:先来先服务、优先级调度、最短作业优先、遗传算法、模拟退火
- 资源管理:资源监控、弹性伸缩、配额管理
- 服务治理:服务发现、熔断降级、负载均衡
成本优化:
- 云仿真成本构成:计算、存储、网络、软件许可
- 成本优化策略:资源选型、自动伸缩、混合云、Spot实例
- 成本监控和预算管理
工程实践:
- Python实现云仿真平台核心组件
- REST API设计和客户端SDK开发
- 完整的案例实战演练
11.2 课后习题
基础题
习题1:解释IaaS、PaaS、SaaS三种云计算服务模型的区别,并举例说明在工程仿真领域的应用场景。
习题2:什么是弹性伸缩?请描述基于阈值的弹性伸缩策略的工作原理,并说明冷却时间的作用。
习题3:比较先来先服务(FIFO)和优先级调度两种算法的优缺点,说明在什么场景下应该选择哪种算法。
进阶题
习题4:设计一个混合云仿真架构,要求:
- 敏感数据在私有云处理
- 大规模计算任务在公有云执行
- 实现数据和任务的安全传输
- 绘制架构图并说明各组件职责
习题5:实现一个改进的任务调度算法,要求:
- 综合考虑任务优先级、预估执行时间和资源需求
- 实现负载均衡,避免某些节点过载
- 支持任务抢占(高优先级任务可以中断低优先级任务)
- 编写Python代码并进行测试
习题6:分析以下场景的成本优化方案:
- 某企业每月需要运行1000个仿真任务
- 每个任务平均需要8核CPU、32GB内存,运行4小时
- 其中20%的任务是紧急任务,不能中断
- 80%的任务可以容忍中断
- 设计最优的资源配置方案,估算月度成本
实践题
习题7:基于本主题提供的代码框架,完成以下功能扩展:
- 添加任务取消功能
- 实现任务重试机制(失败任务自动重试3次)
- 添加任务执行日志记录
- 编写单元测试验证功能正确性
习题8:使用Docker和Docker Compose部署一个简单的云仿真平台:
- 包含任务服务、调度服务和计算节点
- 使用Redis作为消息队列
- 使用PostgreSQL存储任务数据
- 编写docker-compose.yml文件
习题9:设计并实现一个简单的Web界面,用于:
- 提交仿真任务
- 查看任务列表和状态
- 查看平台资源使用情况
- 可以使用Flask或Django框架
11.3 拓展阅读
推荐书籍:
- 《云计算:概念、技术与架构》—— Thomas Erl
- 《微服务设计》—— Sam Newman
- 《Kubernetes权威指南》—— 龚正等
- 《云原生架构白皮书》—— 阿里云
推荐论文:
- “A Survey on Cloud Computing for Engineering Simulation”
- “Task Scheduling Algorithms in Cloud Computing: A Review”
- “Cost Optimization Strategies for Scientific Workflows in the Cloud”
在线资源:
- AWS/Azure/阿里云官方文档
- Kubernetes官方文档
- Docker官方文档
- FEniCS项目文档(开源仿真平台)
11.4 下节预告
在下一个主题中,我们将探讨边缘计算与仿真,学习如何将仿真能力下沉到边缘设备,实现低延迟、高可靠的实时仿真应用。主要内容包括:
- 边缘计算架构和特点
- 边缘-云协同仿真
- 5G时代的实时仿真应用
- 工业物联网中的边缘仿真案例
本教程完
感谢阅读!如有问题或建议,欢迎交流讨论。
2. 为每个任务找到合适的节点
3. 分配任务并更新状态
“”"
scheduled = []
    for task in self.task_queue[:]:  # 复制列表避免修改迭代
        for node in compute_nodes:
            if node.can_accept_task(task):
                if node.assign_task(task):
                    self.task_queue.remove(task)
                    self.running_tasks.append(task)
                    scheduled.append((task, node))
                    break

    return scheduled
### 9.2 调度策略对比

代码中实现了三种调度策略,各有优缺点:

| 策略 | 优点 | 缺点 | 适用场景 |
|-----|------|------|---------|
| Priority | 紧急任务优先 | 低优先级可能饥饿 | 有明确优先级的生产环境 |
| FIFO | 简单公平 | 短任务等待长任务 | 批处理作业 |
| Fair | 资源均衡 | 实现复杂 | 多租户环境 |

---

## 案例实战

### 10.1 案例1:基础云仿真平台演示

**场景**:创建一个包含3个计算节点的云仿真平台,提交5个不同类型的仿真任务。

**代码运行结果**:
============================================================
云仿真平台初始化
添加计算节点: Node(node-0, standard, CPU:16/16)
添加计算节点: Node(node-1, high_memory, CPU:32/32)
添加计算节点: Node(node-2, gpu, CPU:16/16)
提交任务: 020e9815
类型: heat
优先级: 3
预估CPU: 4.0核
预估内存: 4.0GB
预估时间: 100.0秒
调度完成: 5个任务已分配
任务f9cd6f3a -> 节点node-0
任务0c0b4bee -> 节点node-0
任务020e9815 -> 节点node-1
任务c43bd5b2 -> 节点node-1
任务29a64f93 -> 节点node-0
**结果分析**:
- 调度器成功将5个任务分配到3个节点
- 高优先级任务(priority=1)优先被调度
- 资源需求大的任务被分配到高内存节点

### 10.2 案例2:调度策略对比

**场景**:比较三种调度策略(priority、fifo、fair)在相同任务集下的性能。

**可视化结果**:
- **总执行时间**:Priority策略通常最短,因为高优先级任务先执行
- **平均等待时间**:Fair策略通常最优,平衡了各任务的等待时间
- **完成任务数**:三种策略在资源充足时相同

**结论**:
- 生产环境推荐使用Priority策略
- 批处理场景可使用FIFO策略
- 多租户环境推荐使用Fair策略

### 10.3 案例3:资源弹性伸缩

**场景**:模拟工作负载波动,观察自动伸缩的效果。

**实验设置**:
- 初始节点数:1
- 负载变化:低负载(0-15步)→ 高负载(15-35步)→ 中等负载(35-50步)

**观察结果**:
1. 高负载期间,系统自动添加节点(最多5个)
2. 负载降低后,系统自动移除节点
3. CPU利用率维持在合理范围(30%-70%)

**关键指标**:
- 扩容响应时间:约2-3个时间步
- 缩容响应时间:约5-10个时间步(保守策略)
- 资源利用率提升:约40%

### 10.4 案例4:微服务架构

**架构图说明**:
- **API Gateway**:统一入口,处理认证、限流
- **Task Service**:任务管理
- **Scheduler Service**:任务调度
- **Resource Service**:资源管理
- **Result Service**:结果管理
- **Message Queue**:解耦服务间通信
- **Compute Nodes**:实际执行仿真的工作节点

**优势**:
- 各服务独立部署和扩展
- 故障隔离
- 技术栈灵活

### 10.5 案例5:成本分析

**成本构成分析**:
- 计算成本占主要部分(60%-80%)
- Spot实例可节省50%-70%的计算成本
- 存储成本相对较低

**优化建议**:
1. 使用Spot实例运行容错性好的任务
2. 长期稳定负载使用预留实例
3. 自动伸缩避免资源浪费

---

## 总结与习题

### 11.1 知识点总结

本主题系统介绍了云计算与仿真即服务(SaaS)的核心概念和技术:

**核心概念**:
1. 云计算服务模型(IaaS、PaaS、SaaS)
2. 云部署模型(公有云、私有云、混合云、多云)
3. 容器化与容器编排技术

**架构设计**:
1. 分层架构设计(接入层、网关层、服务层、计算层、存储层)
2. 微服务架构原则
3. 服务间通信模式

**关键技术**:
1. 任务调度算法(FCFS、SJF、优先级、负载均衡)
2. 启发式优化算法(遗传算法、模拟退火)
3. 资源弹性伸缩策略
4. REST API设计规范

**成本优化**:
1. 云成本构成分析
2. 实例选型优化
3. 自动伸缩成本控制
4. 混合云成本优化

### 11.2 最佳实践

**云仿真平台设计原则**:
1. **松耦合**:各组件独立部署和扩展
2. **容错性**:单点故障不影响整体服务
3. **可观测性**:全面的监控和日志
4. **安全性**:认证、授权、加密
5. **成本意识**:持续优化资源使用

### 11.3 习题

**理论题**:

1. 比较IaaS、PaaS、SaaS三种服务模型的优缺点,并说明在工程仿真场景中如何选择。

2. 解释以下调度算法的适用场景:
   - 先来先服务(FCFS)
   - 最短作业优先(SJF)
   - 优先级调度
   - 负载均衡调度

3. 设计一个云仿真平台的弹性伸缩策略,要求:
   - 响应时间小于2分钟
   - 资源利用率维持在60%-80%
   - 避免频繁扩缩容

**编程题**:

4. 扩展`TaskScheduler`类,实现一个支持任务依赖的调度器。例如:任务B必须在任务A完成后才能开始。

5. 实现一个简单的云仿真平台REST API服务器(使用Flask或FastAPI),支持任务提交、查询、取消功能。

6. 编写一个成本优化器,根据历史任务数据预测未来的资源需求,并推荐最优的实例类型组合。

**思考题**:

7. 在云仿真平台中,如何平衡成本和性能?讨论不同业务场景下的取舍。

8. 混合云架构在工程仿真中有哪些优势和挑战?如何设计数据同步策略?

9. 随着边缘计算的发展,云仿真平台如何与边缘计算结合?有哪些应用场景?

### 11.4 拓展阅读

**推荐书籍**:
- 《Cloud Native Patterns》: 云原生架构模式
- 《Designing Data-Intensive Applications》: 数据密集型应用设计
- 《Kubernetes in Action》: Kubernetes实战

**在线资源**:
- AWS/Azure/阿里云官方文档
- CNCF(云原生计算基金会)项目
- FEniCS Project:开源有限元计算平台

**开源项目**:
- Kubernetes:容器编排
- Apache Airflow:工作流调度
- Celery:分布式任务队列

---

## 附录:完整代码清单

本主题包含以下代码文件:

1. **实例一_云仿真平台模拟.py**:完整的云仿真平台模拟代码,包含6个案例
2. **案例2_调度策略对比.png**:调度策略对比可视化
3. **案例3_弹性伸缩.png**:弹性伸缩过程可视化
4. **案例4_微服务架构.png**:微服务架构图
5. **案例5_成本分析.png**:成本分析图表

**运行环境要求**:
- Python 3.8+
- NumPy
- Matplotlib
- 标准库:uuid, datetime, enum, json

**运行命令**:
```bash
python 实例一_云仿真平台模拟.py
本教程由Python仿真教学专家编写,仅供学习交流使用。

openEuler 是由开放原子开源基金会孵化的全场景开源操作系统项目,面向数字基础设施四大核心场景(服务器、云计算、边缘计算、嵌入式),全面支持 ARM、x86、RISC-V、loongArch、PowerPC、SW-64 等多样性计算架构
更多推荐
 8
 0
- 0


 已为社区贡献4条内容

所有评论(0)